
Time flies so fast.
Time flies so fast. It's November.
Busiest time of the year?
14 November, 2026 12:14AM by Junichi Uekawa

14 November, 2026 12:14AM by Junichi Uekawa

The upcoming Debian 13.8 point release will be the foundation of the first release of Debian Edu 13.
This is a call for testing, we are interested in your feedback.
See our Debian Edu 13 status page on the Debian Wiki:
https://wiki.debian.org/DebianEdu/Status/Trixie
Debian Edu comes with the Debian Edu manual, it can be found at:
https://jenkins.debian.net/userContent/debian-edu-doc/debian-edu-doc-en/...
Please either directly submit bugs to Debian's bug tracker (package: debian-edu-config); talk to us on IRC #debian-edu on irc.debian.org or write to the Debian Edu mailing list.
[1] https://cdimage.debian.org/debian-cd/current/amd64/iso-bd/debian-edu-13....
[2] https://wiki.debian.org/DebianEdu/HowTo/TestInstallVirtualMachine#Varian...
[3] https://release.debian.org/proposed-updates/stable.html
[4] https://jenkins.debian.net/userContent/debian-edu-doc/debian-edu-doc-en/...
13 November, 2026 10:46PM by sunweaver
Welcome to the October 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third parties to come to a consensus on whether a build was compromised or not.
As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
In this month’s report, we cover:
SOURCE_DATE_EPOCH specification updatesJohannes Schauer Marin Rodrigues (josch) reported an issue to the GNU tar mailing list where creating PAX-format sparse tar archives produces unreproducible outputs. Specifically, when GNU tar generates a PAX archive containing a sparse file it embeds the process ID into the member filename path structure (e.g. ./GNUSparseFile.<pid>/<filename>). Because process IDs vary between build runs, however, archiving identical sparse input files yields different binary outputs.
In his report, Johannes outlined potential workarounds, such as running tar inside an unshared PID namespace where the process ID is pinned to 1, and proposed that GNU tar either omit the PID by default or provide a command-line flag to suppress it. Full details can be found in the post itself, and Johannes also filed the bug in Debian for completeness.
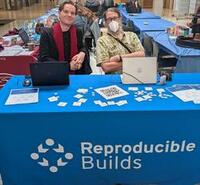
Reproducible Builds was present at SeaGL in Seattle, WA, on October 23rd & 24th. Thanks to everyone who attended and spoke with us!
Members of the Reproducible Builds project attended SeaGL (the Seattle GNU/Linux Conference) in Seattle, WA, on October 23rd & 24th. It was a fantastic opportunity to connect with local community members, discuss software supply chain security and share updates on build verification tooling. Thanks to everyone who stopped by our sessions or spoke with us during the event.
Founded in 2013, SeaGL is an annual free-as-in-freedom, grassroots technical summit dedicated to spreading awareness, community engagement and practical knowledge about free software, open hardware and libre culture.

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 333, 334, 335 and 336 to Debian:
New features:
dumppdf binary being called dumppdf.py on the host/runtime system. […]Bug fixes:
Codebase improvements:
Misc:
In addition, Johannes Schauer Marin Rodrigues added support for POSIX.1-2001 PAX headers in the .tar file comparator […] and Vagrant Cascadian proposed an update in diffoscope in GNU Guix to version 335.

In Debian this month, 20 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. One issue type was updated to reflect that Debhelper ‘compat’ level 14 is no longer experimental. […]
In addition, Vagrant Cascadian performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included clhep, tea-cli, argparse-manpage, ruby-timers, mandos and cdebootstrap.

Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.
SOURCE_DATE_EPOCH specification updatesAs announced in last month’s report, further work has been done by Bernhard M. Wiedemann regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes were originally submitted as merge requests on Salsa, and many of these have been approved or otherwise collapsed.
Bernhard’s proposed modifications were independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests; as Bernhard writes, “The other MRs could still use feedback from more people before December”. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list.
The SOURCE_DATE_EPOCH specification was first published in 2015 and updated in 2017.
On our mailing list this month:
Robin Candau posted to the list to announce the revival of a central repository to share reproducible builds patches. Following discussions at this year’s Reproducible Builds summit, Robin and Bernhard M. Wiedemann brought back a repository originally created a decade ago to collect distro-specific fixes in a unified location. Bernhard has already populated the repository with reproducible builds patches from openSUSE, while Robin has contributed patches from Arch Linux and has invited maintainers from other distributions to request push access.
Last month, Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism. The conversation continued this month with a number of proposals.
Jeremy Bícha wrote that he was seeking assistance with a reproducibility failure in GNOME’s libsoup library when built using debrebuild. Filed as Debian bug #1126440, the issue stems from a Meson build system check that inspects Apache and its local configuration during the build process, which fails inside debrebuild environments. His query solicited a number of replies (including one from an AI agent).
Janneke Nieuwenhuizen and Ekaitz Zarraga announced two releases of GNU Mes: version 0.27.2 and version 0.28. GNU Mes is a Scheme interpreter and C compiler created to facilitate bootstrapping the GNU system without relying on opaque binary blobs, serving as a core component of the Bootstrappable Builds effort. Version 0.27.2 serves as a bug-fix release adding compatibility for the recently-released GCC 16 and NYACC versions 2.02.4 and 3.00.0, etc. whilst version 0.28 introduces a major overhaul of the core interpreter.
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Bernhard M. Wiedemann:
Chris Lamb:
js8call.pywps.php-nesbot-carbon.kicad-library-utils.ros-dynamic-reconfigure.golang-github-anacrolix-log.complexity.node-uplot.python-poetry-dynamic-versioning.Jochen Sprickerhof:
open-build-service.Johannes Schauer Marin Rodrigues:
Vagrant Cascadian:
Zackary Loevseth:
In addition, two build failure bugs were reported by Jochen Sprickerhof.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
IRC: #reproducible-builds on irc.oftc.net.
Mastodon: @reproducible_builds@fosstodon.org
Mailing list: rb-general@lists.reproducible-builds.org

Christoffer Stjernlöf posted about the Fox Game, an old Norse asymmetric board game (seemingly also called “halatafl”) where twenty sheep try to outsmart two foxes and get to the other side. His AI uncovered some interesting insights, but left the question open as of whether the foxes or the sheep actually win with perfect play (the general sentiment in his family was that winning with the foxes was easy). This was too tempting for me to leave on the table, so I set out to make a strong solve.
Since I don't know this game myself, I've stayed with the rules he describes even when they differ from e.g. Wikipedia (in particular, I do not use forced fox jumps, or multi-jumps); the only real change is that I don't have a 40-move draw rule, any position that is a forced win for one of the sides would be a win no matter how long it would take. (I consider this just an implementation detail in his AI, although morally, I consider a draw a loss for the sheep.) You might want to read his post to get the full rules, because I'm not going to repeat them here.
The results first: The sheep win with perfect play, even with only 19 sheep (remove one on the flank), or 18 if they are allowed to go first. Even with only 9 sheep (the minimum possible that isn't an instant win for the foxes), the sheep can force a draw right from the start. With one fox, 11 sheep suffice for a forced win. (The draw margin is seemingly so large because one fox can just camp in the last spot in the pen, and it's hard to force it away without getting harassed by the other fox, unless you have lots of sheep.)
The rest is about the implementation. I'll skip over a lot of wrong turns, and unsurprisingly, there were a lot of bugs to iron out, but hopefully, it got to a good place in the end. :-) I started out trying to make something very simple, and it worked for the first few cases, but then things got more complicated than I would have liked in the end. Still only at ~1000 lines of code, though, with no dependencies.
The board has 33 squares. I tried a few different ways of represent the state of the game, and ended up on a simple bitboard representation: There's a 64-bit bitmap representing where there are sheep, and another bitmap representing where there are foxes. Since there's plenty of room in there, I use a spare bit to represent side-to-move. This is compact (which mattered a lot earlier on, but not as much later), easy to iterate over, and has little redundancy, so it's easy to keep valid. You need fast 64-bit population count and bit-scan instructions, but a) that's common now everywhere, and b) I decided fairly early that I wanted to require BMI2 anyway.
The bit order mostly doesn't matter; I just started at top-left and went from there. All it really influences is square iteration order. There's a small tweak in that I store the right half of the board mirrored (reverse x order) for symmetry purposes; more on that below.
I just typed in every possible move from every square into an array, then verified by generating some SVGs that I hadn't made any typos (I had). In retrospect, I should have done something more automated; it would have been less painful.
The moves for sheep are just “you can go to X, Y or Z”. The moves for foxes are “you can go to X or Y, or you can go to Z if there's a sheep at W (which will be eaten)”. The move generator mostly just looks up the source square and tests every move. For the sheep, I make an easy test using bitboards; for the foxes, I could probably do something similar, but the jump moves proved a bit tricky (even with PEXT/PDEP) and I didn't end up using it.
This is the part that really determines the geometry of the board (apart from debugging display). Everything else is pretty much geometry-agnostic.
There's a little over 2^41 possible board states (this includes some illegal positions as well as some situations that could never arise during actual gameplay, such as a fox being stuck at C1 with a row of sheep ahead of it), and I want to remember all of them. With that many positions, I figured I needed a fairly compact representation. I needed to store that a position could be sheep win, fox win or a draw, and then there was a fourth “invalid” state that was useful for internal reasons, so that maps exactly to two bits per position. (A tablebase intended for distribution could be compressed to less using the usual tricks of entropy coding, skipping half of the positions, or similar.)
This means we need to give a number to every possible position, ideally one with no collisions and no holes. I learned about combinatorial number systems which fit the bill exactly; given e.g. “we have 33 squares and 15 pieces”, it gives a dense mapping of positions from board to ID (ranking) and the opposite (unranking). (I made some fairly fast ranking and unranking algorithms, which may or may not have been novel, but it turned out I didn't actually need fast unranking after some other optimizations.) There are some extra complications in that there are two types of pieces, but you can solve them in a number of ways.
On a macro level, I store everything with 9 sheep and 1 fox first, then 9 sheep and 2 foxes, 10 sheep and 1 fox, and so on. This gives beautiful locality (a single move can never remove more than one sheep, and only extremely rarely more than one fox), allowing me to just mmap everything and let the kernel deal with it, even though I only had 256GB of RAM and the total set was larger (329,870,110,455 bytes after the symmetry optimizations below).
mmap is almost never the right answer, but again, I was trying to go for simplicity. It certainly brought me pain, though, and perhaps some more explicit I/O would have been better.
The board is left-right symmetric (with an odd number of columns, so that there is a middle column that is neither “left” nor “right”). I had hoped to just ignore this, but eventually the gains became too important to ignore, so I conceded.
The basic idea is that I ranked the board twice, both as itself and mirrored (mirroring is just a couple of masks and shifts, given my representation), and picked the key that was the smaller as canonical. This reduced the number of positions I needed to look at to a bit over 50%, as expected, but it does nothing to the storage/RAM requirements; the new rank is not dense and the “illegal” (non-canonical) positions are spread out a bit all over the place (although of course near the low and high ends of values, it works much better).
As a tweak, I chose to compute all 33+281 canonical fox positions and renumbered using those placements as an assumption. This slashes ~95% of the waste, which is good enough; you can still rank a nonconical position if the foxes are symmetric about the center (or if there's only one fox and it's in the middle!), though.
You can improve on this by making the macro-splitting finer; instead of having a chunk for e.g. “10 sheep, 2 foxes”, you could have one with “5 sheep in left, 0 foxes in left, 1 sheep center, 1 fox center, 4 sheep in right, 1 fox in right” and demand that there are more sheep in left than right. However, you still get problems when the number is balanced, you'd need finer splitting etc.. The gains are small enough that I didn't see the point in doing this, and it tends to be a place where it's easy to introduce bugs.
I imagined calculating the exact number of positions up to symmetry would be an interesting exercise somehow, but I suppose it just immediately falls to Burnside's lemma as soon as you know how to count positions at all.
Now that we have positions and moves and a way to store results, we want to know how to find the result for the starting position (and ideally also all other positions).
My first attempt just did a depth-first search, caching as it went. This worked for the earlier stages but was generally a disaster; it ran out of stack easily (even with 8 GB—eight gigabytes of stack), and had problems with figuring out loops. (It didn't loop infinitely, but was prone to declaring loops where one side could break out of the loop by winning. I had a nasty hack to fix that, but it didn't really feel good.)
What I did instead was propagating results one step at a time. For each possible position:
If from a given position you know you can immediately win (e.g., the sheep reach the pen, or the fox eats the last relevant sheep), mark it as such.
If you can, in one move, reach a known-won position, mark your position as won (for the side to move). Similarly, if you can only reach known-lost positions, mark your position as lost.
Repeat #2 over and over again until you no longer have changes.
This was simple but still inefficient; I typically needed 40–80 passes for each chunk (where a chunk is something like “all positions with 15 sheep, 2 foxes”). However, it was super-easy to parallelize; I have 64 cores and could just hand out reasonable independent sub-chunks, you don't even need locking or atomic operations on the result set.
The correct way of doing this is retrograde analysis (replace #2 with doing backwards moves) and I assume this would have made the calculation roughly ten times as fast. But I only needed ~36 hours for the actual run (plus numerous pre-runs that failed for various reasons!), so I never got to this. After all, I wanted something simple to begin with.
Since I only store win/draw/loss (WDL) for each position (also known as a “bitbase” in chess tablebases), it's not easy to know what the fastest way to win is; just that “this move does not mess it up, the other side still can't force a draw”. However, in practice, you could just do reasonable-looking moves that don't regress the position, and take forward moves whenever you can (i.e., do sheep pushes if that still wins).
I made a simple alpha-beta searcher that tries to get win distances using the bitbase as a guide, which was a really fun challenge! It can find wins when they're perhaps ~20 ply (10 moves for each side) away, depending a bit on how narrow the win is (if there are only a few ways to win, it will obviously have to search a much smaller tree). Ultimately, though, alpha-beta for finding exact mate scores is just a losing game, since even perfect move ordering will only give you a sqrt() improvement over pure minimax.
Perhaps making DTZ (distance-to-zeroing, referring to zeroing the draw move counter in e.g. chess) bases would be possible without breaking the bank on storage space; I would assume that usually, you can force some sort of progress pretty fast, at least as the sheep.
I made a very rudimentary interface to the database; the UI isn't very nice, and it largely relies on hovering (which doesn't work all that well on mobile) but I didn't want a polished game-player, just to know the answer. :-) You can try it out at https://sheep.sesse.net/, although I don't envision keeping it up forever. Perhaps someone can gain new insight from it and become an expert player, although strong solves are rarely very insightful in themselves due to the brute-force nature. At least we've conclusively settled (again, under this ruleset!) that the sheep win with perfect play.
Earlier, I would publish the source, but these days, the only ones who would be reading it would be the AI beast (fox?), and I'm not really so interested in that. :-) I'm definitely open to answering questions if anyone should have them; contact information at my home page as usual.
In the recent years, I've been configuring and
building GNU Emacs from source, specifically the
master branch of the emacs.git repository.
Doing so allows me to use and test latest Emacs
features, test my Emacs Lisp code with the laest
developments in Emacs, and easily contribute my
own changes to Emacs.
Before we start, I recommend reading the INSTALL
file in the Emacs source repository for building
Emacs from source tarballs, and also INSTALL.REPO
for details about building Emacs from its source
repository. The information provided here were
built upon the details documented in those files.
When in doubt, consult those files as the main,
authoritative source of information for how to
build Emacs from source.
To build GNU Emacs from its source repository, we
first need to install the various required tools
and build dependencies of Emacs. On Debian-based
systems, this can be done using apt. First, we
need to add the source packages for the current
release of our Debian-based distribution in apt's
configuration by adding the corresponding deb-src
lines in an apt source list file. For currently
existing and older Debian releases, that would be
done by adding a corresponding deb-src line for
each deb line in /etc/apt/sources.list, such as:
deb http://deb.debian.org/debian/ trixie main
deb-src http://deb.debian.org/debian/ trixie main
In systems with recent apt versions with so-called
modernized sources that might look editing a file
like /etc/apt/sources.list.d/debian.sources and
adding deb-src to the Types lines:
Types: deb deb-src
URIs: http://deb.debian.org/debian/
Suites: trixie
Components: main
Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg
Then run sudo apt update to have apt download
package information from the configured sources.
We can now run sudo apt build-dep emacs to have
apt download and install the build dependencies of
Emacs. Debian-based distributions have packages
for a few different configurations of Emacs, like
emacs-pgtk with PGTK support for Wayland, and
emacs-nox for Emacs without GUI support, which
we can use with apt build-dep to download the
specific dependencies of those configurations.
After installing Git using sudo apt install git
if not already installed, we're now ready to clone
the Emacs source repository from GNU Savannah:
git clone https://https.git.savannah.gnu.org/git/emacs.git
We can add --depth 1 to make a shallow clone of
the repository, if we don't care about having a
complete log of previous commits to the Emacs
repository (shallow clones are much faster).
If cloning over HTTPS is slow, we can try cloning over Git's own protocol (with the caveat that the repository is cloned over an insecure channel) or over SSH if we have a Savannah account, using one of the following URLs instead of the one above:
git://git.git.savannah.gnu.org/emacs.git
ssh://git.savannah.gnu.org/srv/git/emacs.git
We now change to the Emacs repository directory
we just cloned, and run the autogen.sh script
once to generate the configure script, which
we will use to configure Emacs to our liking:
cd emacs
./autogen.sh
To configure Emacs, the simplest approach is to
run configure without any additional options,
to have it use the defaults. We can get a list
of available configuration options by running:
./configure --help
As I rebuild Emacs frequently, I normally don't
"install" it, but for a typical setup, we'll
want to specify the installation directory using
--prefix, e.g.:
./configure --prefix=$HOME/.local
Later, make install will install Emacs under
the specified directory.
By default, some of the files (such as *.el)
will be compressed during installation. We can
prevent that using --without-compress-install.
For my builds, I always use these configuration options:
--without-gconf
--without-gsettings
--without-gpm
--with-native-compilation
As I don't use the GNOME desktop, the GConf and GSettings integrations are always more trouble than useful for me, so I disable them. Further, I disable the GPM support, since I never use the mouse when using Emacs in the terminal. Lastly, I explicitly enable native compilation support.
In Wayland environments, I usually use PGTK:
--with-pgtk
And in X11 environments (e.g. EXWM), I either use the Lucid toolkit:
--with-x-toolkit=lucid --with-xaw3d
Or no toolkit at all:
--with-x-toolkit=no --without-xaw3d
Later after building Emacs, we can view the
configuration options in Emacs by inspecting
the system-configuration-options variable.
After running ./configure, we can now finally
build Emacs by running make. The first build
will take a while, since all of Emacs is being
built from scratch. Subsequent builds will
generally be faster.
We can optionally run make install to install
Emacs into the prefix specified earlier, or the
default /usr/local. Note that this step might
require using sudo if our user doesn't have
write permission for the prefix.
After building Emacs, we run it either from
the install location if we ran make install
earlier, or directly from the source repository.
Currently, Emacs's build system makes a symlink
to the latest built binary in the repository at
src/emacs, and for emacsclient and other
auxiliary binaries under the lib-src directory.
When skipping make install, we might still want
to be able to easily launch Emacs from anywhere
by typing emacs. We can do that by making
symlinks to emacs and its auxiliary binaries
inside a directory in our $PATH, such as
$HOME/.local/bin, like so:
cd $HOME/.local/bin
ln -s $HOME/src/emacs/src/emacs .
for e in \
 ebrowse emacsclient etags make-docfile\
 make-fingerprint hexl rcs2log; do\
  ln -s $HOME/src/emacs/lib-src/$e .; done
For non-install setups like this, I augment
Info-directory-list in my init file with
the location of the info manuals in the
repository to make them known to Emacs:
(defvar Info-directory-list)
(with-eval-after-load 'info
  (setq
   Info-directory-list
   `(,@Info-directory-list
     ,(expand-file-name
       (convert-standard-filename "info/")
       source-directory)
     "/usr/share/info/")))
We can pull in the latest changes in the Emacs
repository using git pull, then rebuild our
Emacs by running make.
Occasionally, rebuilds may fail due to bad
interaction of changes with leftover build
artifacts. In such cases, the easiest thing
to do would be a make bootstrap for an
almost-from-scratch build. On even rarer
occasions, make bootstrap might also fail.
We would then want to run git clean -xdf to
remove every file that's not tracked by Git,
as if we freshly cloned the repository.
In such cases, we would need to configure the
build again using ./configure and provide the
desired options before running make again.
Protesilaos's similar post from early 2025 was part of the inspiration for writing and sharing my version:
https://protesilaos.com/codelog/2025-03-22-emacs-build-source-debian/Lastly, to reiterate, Emacs's own INSTALL and
INSTALL.REPO files for building from source:
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL.REPO
Take care, and so long for now.

The following contributors got their Debian Developer accounts in the last two months:
The following contributors were added as Debian Maintainers in the last two months:
Congratulations!
13 November, 2026 10:00AM by Jean-Pierre Giraud
Contributing to Debian is part of Freexian’s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.
Debian has started the transition to add Python 3.15 as a supported version alongside 3.14, which is still the default version. Stefano uploaded Python 3.15.0 final to unstable.
Maximiliano Curia has been test-rebuilding the archive in Debusine with Python 3.15 as a supported version and prepared some patches to dh-python to smooth over some common failure points. Stefano reviewed these MRs, applying some and implementing alternative approaches for some of the issues.
Debian only has multiple supported Python versions during the transition to a new version, and typically this shows up some bugs in packages. This time was no different, the common failure was many packages that installed intermediate build artifacts into the Python module tree. Some of these artifacts would differ between Python versions. We decided to detect both of these and fail the package build, rather than silently ship garbage in the binary packages. Colin helped to fix quite a bit of the build fallout from this.
The recent GSS-API package split has largely gone relatively smoothly, but there was a subtle problem for people switching from one variant to the other: installing the replacement packages followed by purging the old one would cause some configuration files to disappear. Colin fixed this, and also reviewed and merged some autopkgtest contributions from Andreas Hasenack to make sure that this doesn’t regress in future.
13 November, 2026 12:00AM by Anupa Ann Joseph
The diffoscope maintainers are pleased to announce the release of diffoscope
version 339. This version includes the following changes:
[ Jay Burstin ]
* Rework including .zip-related differences for .odt files.

[ Chris Lamb ]
* Add some comments to recent OdtFile changes.
* Update copyright years.
You find out more by visiting the project homepage.

My Debian contributions this month were all sponsored by Freexian.
You can also support my work directly via Liberapay or GitHub Sponsors.
I upgraded both openssh and openssh-gssapi from 10.5p1 to 10.6p1, started generating MLDSA44-ED25519 host keys by default now that upstream no longer considers them experimental, and fixed a problem where switching between the normal and GSS-API variants followed by purging the old packages caused some configuration files to disappear.
New upstream versions:
Other build/test failures:
bcrypt-pbkdf = "^0.10.0"Since lots of Python modules use Rust extensions nowadays, we often have to help with upgrades of Rust packages. I did some of this:
Other bugs:
One of my hobbies is typesetting (“engraving”) music, sometimes for my own use, sometimes for teaching, and sometimes for my choir. I’ve used LilyPond for a long time and have got pretty used to it. My workflow was a bit cumbersome, though, usually involving side-by-side editor and PDF viewer windows with some ad-hoc Makefiles and editor macros. I recently discovered the Frescobaldi frontend to LilyPond, and decided I liked it enough to switch over to it. It was already packaged in Debian, but it had a missing desktop entry and icon and missing translations; I fixed those based on a patch set by Joachim Wiedorn. My upload introduced a testing migration problem, which I also fixed.
I upgraded rust-jiter and rust-smallvec to new upstream versions for a new version of pydantic-core. The rust-smallvec upgrade caused an FTBFS in rust-saphyr-parser-bw, which I fixed.
I packaged rust-cargo-cyclonedx for a new version of python-maturin. This needed some porting to work with a new version of rust-cargo-metadata, which I contributed upstream.
I improved the dev/list-rdeps.sh tool used by the Rust team to check build-depends too, which should make it easier for that team to remember Python packages in transitions.
11 November, 2026 10:01AM by Colin Watson
In mid 2025 I bought a Thinkpad X1 Carbon Gen 6 with 1440p display for $350 [1].
It has been working reasonably well for me, but my vision is diminishing so my current setup with the Kitty terminal emulator allows 4 terminals of 153/154 columns and 40/41 rows or 9 terminals of about 101*27. To have this much text I use the minimum font size I can see which is unreadable when I first wake up – which is bad for the “woken by network management system alert” situations. Also 16G of RAM is a bit of a limit, the Thinkpad X1 Carbon has 4G of swap space and it’s all used most of the time. While there’s usually plenty of buffer/cache RAM it does sometimes get to an OOM situation.
Another issue is that the battery is approaching it’s end of life. The “upower -d” command reports the following which might imply that the battery should last more than 80% of the time when it was new, but testing shows that the time I can use it on battery is not much more than half what it was when I bought the laptop, maybe 1/3 of the battery life when new. I used to be able to consistently run the machine on battery for 7+ hours and still have plenty of charge left, now I can’t even get 5 hours.
energy-full:         50.35 Wh
energy-full-design:  57.02 Wh
I could buy a new battery for about $70, but there are plenty of things I can do with that laptop for which 1/3 the designed battery life is more than enough. Also I have a couple of USB-C batteries that are capable of supplying 30W+ to power a Thinkpad X1 Carbon but they are inconvenient and I’d rather have external batteries and an internal battery that will last most of a day.
Below is a table summarising most of the Thinkpads I’ve owned. I really like the Trackpoint on Thinkpads and have not considered buying a laptop without one. I skipped two laptops I bought in the 2000-2002 time period, that was an expensive laptop time for me. Fortunately by 2000 ebay was getting useful so I only ever had to buy one brand new Thinkpad.
| Thinkpad | Purchase Date | Release Year | Price | Price 2025 money | RAM | CPU | Display | Replacement Reason |
|---|---|---|---|---|---|---|---|---|
| 385XD | Jul 1998 | 1998 | $5800 | $12268 | 96M | Pentium MMX 233 | 800*600 | weight screen resolution CPU and RAM |
| T41p | 2003 | 2003 | 1.5G | Pentium M | 1400*1050 | overheating and screen backlight | ||
| T61 | Feb 2010 | 2007 | $796 | $1182 | 5G | Core 2 Duo | 1680*1050 | overheating battery-life and PSU |
| T420 | Oct 2013 | 2011 | $306.35 | $422 | 8G | i5-2540M maybe | 1600*900 | lid hinge broken and generally old |
| X301 | Dec 2017 | 2008 | $0 | $0 | 4G | Core 2 Duo SU9400 | 1440*900 | battery entirely died |
| X1 Carbon Gen 1 | Feb 2018 | 2012 | $289 | $364 | 8G | i7-3667U | 1600*900 | error on proprietary SSD lack of USB-C and screen resolution |
| X1 Carbon Gen 5 | Jul 2022 | 2017 | $575.25 | $644 | 8G | i5-6300U | 1920*1080 | screen resolution and wanted a 2in1 |
| X1 Yoga Gen 3 | Jan 2024 | 2018 | $359.10 | 16G | i5-8350U | 2560*1440 | crashed when on battery | |
| X1 Carbon Gen 6 | Jul 2025 | 2018 | $350 | 16G | i7-8550U | 2560*1440 | RAM and screen resolution | |
| T14 Gen 1 | Oct 2026 | 2020 | $340 | 16G+ | i7-10610U | 3840*2160 |
So I’ve spent $2675.70 on Thinkpads that I used from 2010 until now (not counting the one I just bought), so that’s $160 per annum for the past 16 years and 9 months.
When I convert that to 2025/2026 dollars that’s $3,221 for 16 years 9 months or $198 per annum. So I just need to make this T14 last for 2 years to be spending less than usual.
A while ago I was asked for advice on buying a laptop for an architect to use. I can give good advice for laptops used by programmers and for home use and students but I really don’t know what an architect does and even a description wouldn’t do it justice.
The advice I gave was to buy or borrow a relatively low end laptop, something that costs $400 new or $300 second hand and give it a go. Using it will reveal that it doesn’t do what is desired in some ways, whether it’s screen resolution, RAM, CPU power, storage capacity, physical size/weight, or some combination of them is something you won’t know until you try it. Then after having used a cheap laptop they could buy a laptop for $1500+ (for serious work use by people outside the IT industry buying a new laptop is recommended) knowing what features they really need.
So I have gone through a similar process of buying different laptops and discovering the benefits which has arrived at the T14.
I saw a Thinkpad T14 with 4K display and 16G of RAM on Facebook Marketplace advertised for $400 and they ended up selling it to me for $300 without the SSD and without the PSU. The seller has a business of selling used enterprise gear so he was happy to keep the SSD and PSU for sale with other laptops. I don’t have a need for more laptop PSUs as I have most of the laptops in my fleet charged from 200W+ PSUs that charge multiple devices and I also have a collection of spare SSDs.
$300 for a laptop with 4K display is a good deal. The T14 is significantly better than the T14s because it has one SODIMM socket while the T14s has soldered RAM, so I could expand the RAM to 48G at some future time – but with current prices I bought an 8G SODIMM for $40 so 24G will have to do for now. That gives a total of $340 plus the value of a SSD.
My first tests with the 4K display I set the display scaling to 150% (previously I had 100% which was a little small for some parts of the display). For my current favourite terminal emulator Kitty I had the Terminus font set to 10.5 point and now have it set to 9.0 point. This set of changes took the amount of text displayed in terminals from about 300*80 to about 330*100 while also increasing readability. This is a very significant improvement. If I knew that 4K in a 14″ display would be so good I’d have got it years ago!
The T14 still fits in the pocked of my ScotteVest jacket [2]!
The i7-10610U in my new Thinkpad scores only about 10% faster on Passmark than the i7-8550U in my previous one. That’s disappointing given that Intel had another 3 years of research to develop it and it’s running with faster RAM. The two CPUs have the same TDP so it’s just a 10% performance gain over 3 years and no change anywhere else. If the new CPU had a lower TDP then the small performance increase would be understandable.
When I first booted the system Chrome graphics were corrupted and system performance was bad, after installing the packages firmware-nvidia-graphics and firmware-sof-signed to deal with the kernel errors about not finding firmware the graphics display was correct and the system ran a lot faster. I had forgotten about the issues related to having NVidia and Intel GPUs on the same system that I had dealt with in previous T series Thinkpads.
In the systemd-boot loader.conf file I added “console-mode 0” to prevent the font being ridiculously small for the boot selection.
The battery life seems like it might be a bit less than my previous laptop was when I got it, but it’s definitely better than the previous laptop gives now.
The screen is very shiny, I prefer the screens with matt finish to avoid seeing reflections. The “anti glare” screens for the T14 are for FullHD and worse while the “glossy” screen is the only option for 4K.. Maybe I should investigate one of those hoodie jackets with a hood that’s large enough to cover the screen, they are being sold as a privacy feature but can also be used to avoid reflection. As an aside if you are in an environment with hostile parties then you really shouldn’t block your vision of them.
A problem I previously had with T series Thinkpads which contributed to the replacement of two of them is the screen hinges breaking. This laptop is significantly heavier and more solidly built than the X1 series I’ve been using and opening and closing the screen takes a lot more force. I am now wondering if I’ll be looking for a “for parts” condition Thinkpad on ebay in the future. It seems that cracking the screen is a much more common failure case than breaking the hinges so hopefully there will be spares available. But as my previous T series thinkpads lasted 7, 3, and 4 years this one could be expected to last until 2030 and maybe by then giving it to someone in Vietnam and buying a replacement would be the easiest option.
I thought that going from 2560*1440 to 3840*2160 I would be hitting the diminishing returns range but it seems that there are still further gains to be found in screen resolution for my use, maybe the Apple people with their “Retina” displays are on to something. There are Thinkpad X1 Carbon models with 3840*2400 displays, so maybe that’s something to move on to in a few years. The minimum model with 3840*2400 is the X1 Carbon Gen 9 and there’s the X1 Yoga Gen 6 with an OLED 3840*2400. There’s also the P series which has 16″ 3840*2400 displays which would allow more usable text with the caveat of being much less portable.
It sucks that no-one seems to be making a laptop with more than 3840*2400 resolution. 5120*2160 desktop monitors are common and affordable nowadays. I’m sure that even now I could use more than 3840*2400 in a 14″ laptop and when I was younger I could have benefited from more than 3840*2400 in an 11″ laptop if such hardware had been available.
11 November, 2026 04:25AM by etbe

Ever since I built an AirGradient board back in 2023, I have been more and more conscientious about air quality. Pretty instantly after installing the board in my living room, I realised common habits like cooking can significantly increase the particulate levels in my entire apartment.
Here is a good example of a pretty large (and long-lasting) PM2.5 spike on September 23rd after cooking a meal1:
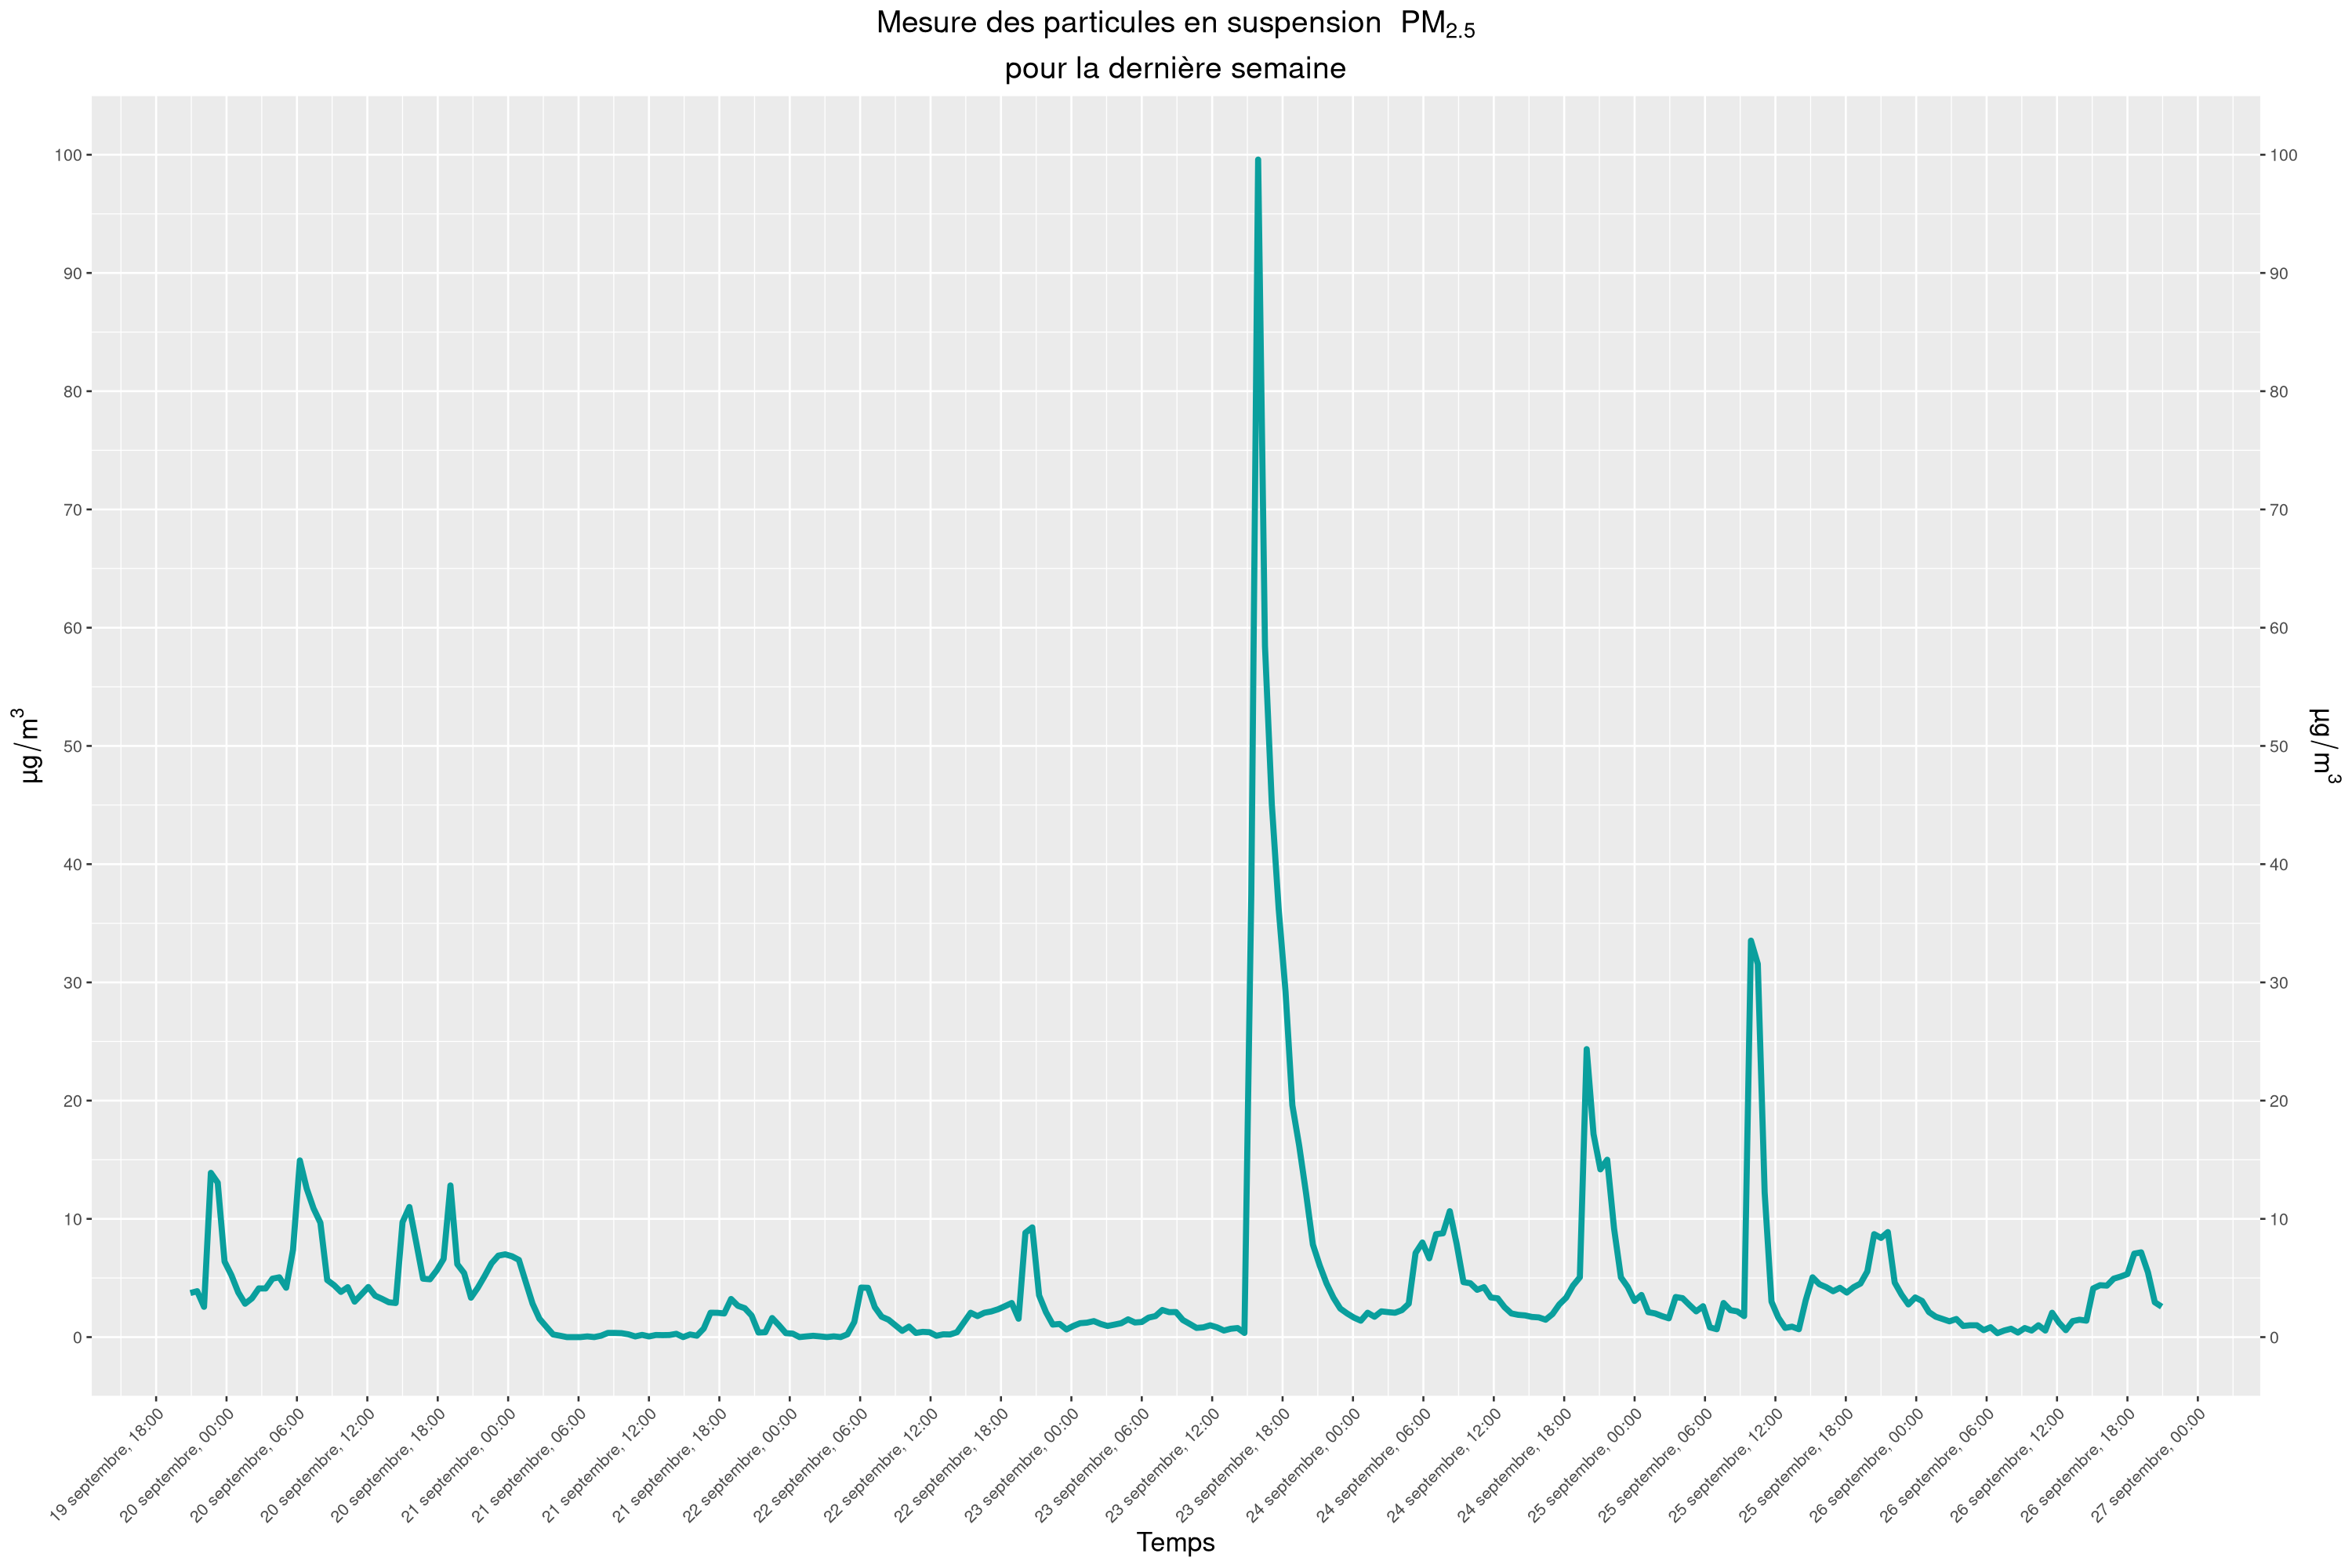
Isn't this crazy? Last time Montreal had such bad outdoor air quality, there were public broadcasts telling people not to go outside and to wear N95 face masks if we absolutely needed to. Inside my apartment though, no one ever told me cooking veggies in a little oil on medium-low2 could make the air I breathe unsafe.
This of course is aggravated by the fact my apartment is pretty much as airtight as it can reasonably be, since winters here are very cold and air infiltrations are a major heat loss source. As such "opening my windows when I cook" is not a viable solution to this problem half of the year.
I first tried solving this issue by tuning my HVAC system. Sadly, its controls don't offer much flexibility3, which means it is not the right tool to respond to short-lived spikes like these. Not only this, but the quality of the air outside is not always good either: Canada now has a forest fire season (we're all doomed) and my neighbors regularly smoke cigarettes right under my HVAC air intake4.
Clearly, the solution to this particular issue was to buy an air purifier. Or at least, that's what a "normal" people would have done. Sadly, these units are expensive, use (expensive) proprietary filters, don't work very well and can be loud.
One of the great inventions of the COVID-19 pandemic is the Corsi-Rosenthal box. Popularised in 2020 by Richard Corsi and Jim Rosenthal, the idea is to make a DIY air purifier by using a large fan to force air through cheap and readily available MERV13 air filters.
The main downsides of regular CR boxes is they are pretty ugly, can be loud depending on the fan used and need to be rebuilt when the filters are changed (they are held using tape).
That's when I stumbled on this amazing design for a silent and sleek CR box sold by The 3D Handyman. Clearly, with a bit of tinkering and a 3D printer, I could also design something sleek, silent and efficient!
Since I was already using MERV13 air filters in my HVAC, I decided to design around 4 vertical "beams" where the filters would slot in. With tight enough tolerances, I figured I could get rid of the complex moving parts in The 3D Handyman's design. I also added M5 threads to screw the top and bottom panels and the TPU feet to elevate the box from the floor.
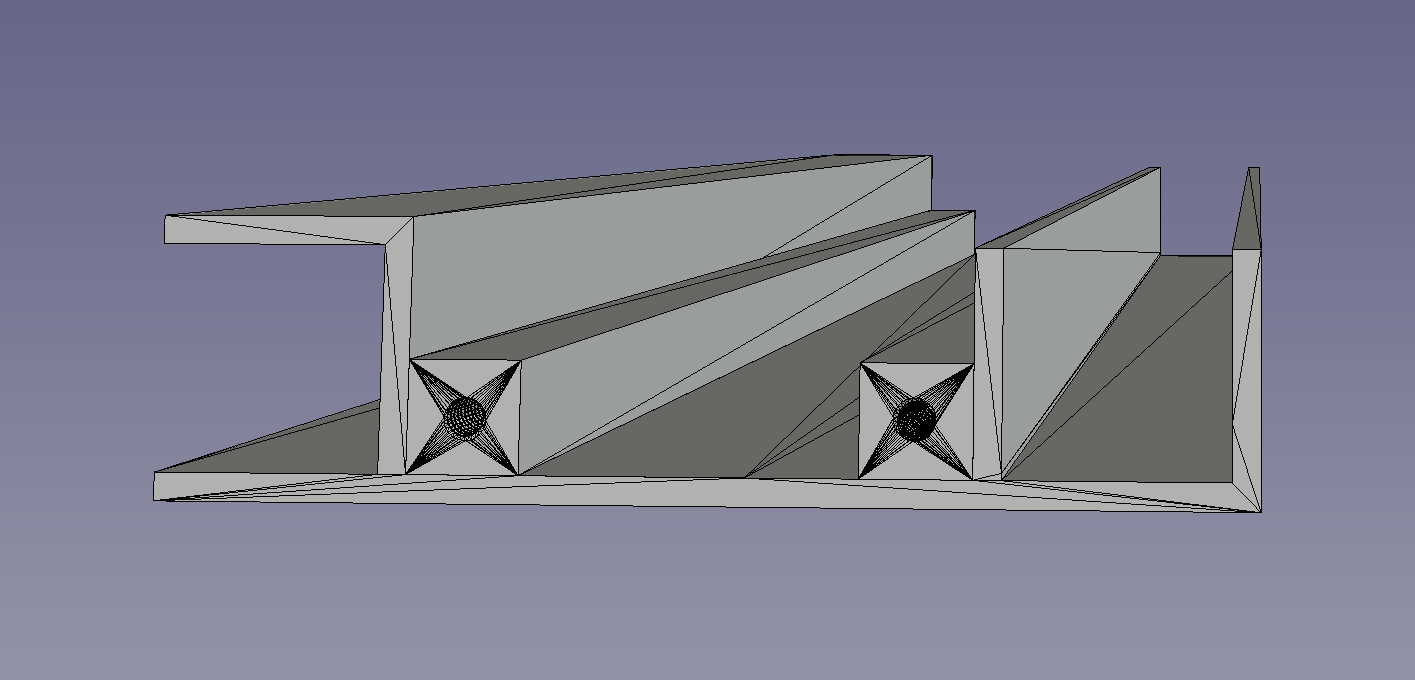
The final result looks like this. I used some foamcore boards I had laying around at work for the top and bottom panels, but any somewhat rigid plastic panels (like coroplast) would also work:
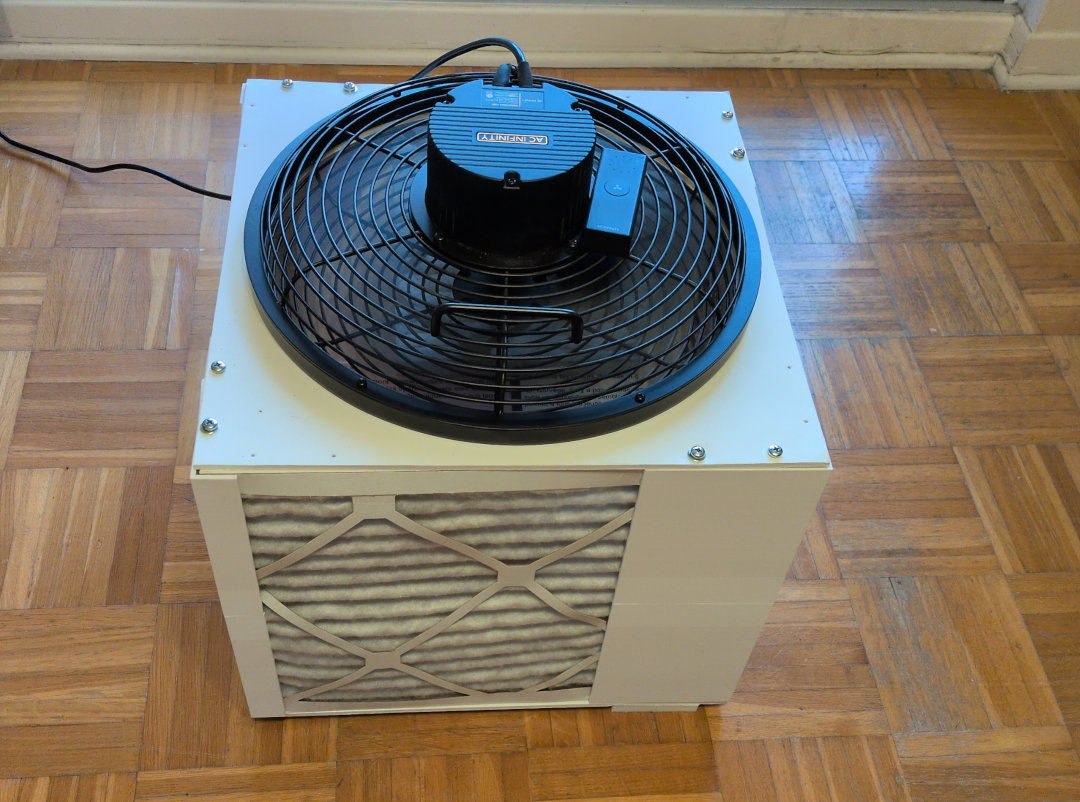 out' position" alt="The whole CR box assembled, with the fan in the 'in -> out' position">
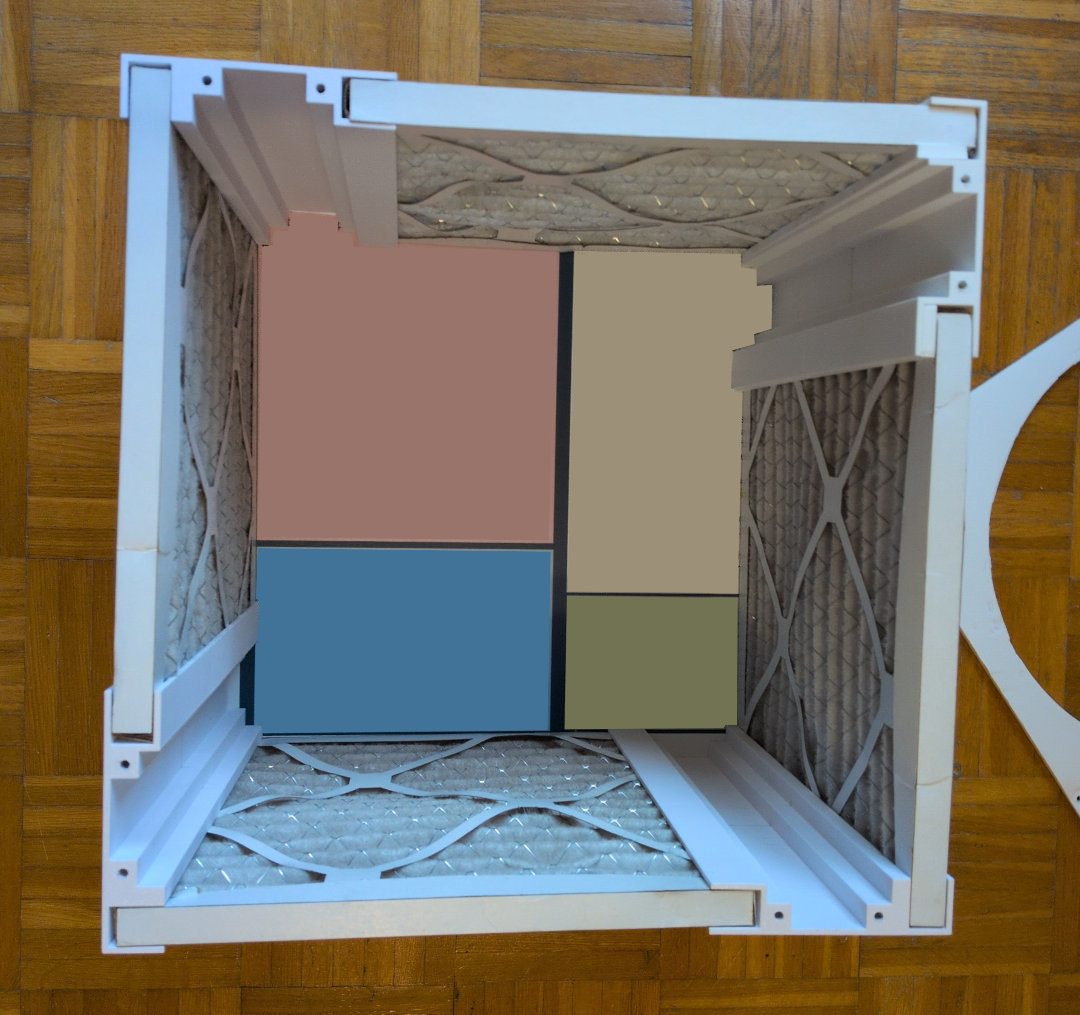
I ended up having to split the "beams" in two and joining them with dowels, as even the largest 3D printers I had access to couldn't print them in one piece.
Here's the cost breakdown for this project (shipping and taxes are included):
Total: 502.19 CAD
Yikes, expensive! But:
The fan is amazing. It is by far the best fan I have ever owned. Not only it is all metal and very quiet, but it is also PWM-controlled via a USB-C controller, which means the speed it runs at can be automated. I have been using it constantly and take it out of the CR box during the summer to be used as a "regular" fan. I like it so much so I am seriously considering buying the 14 inch model.
The 3D printed parts are plastic and they will last me a lifetime.
As mentioned before, the filters are the same I use in HVAC, which means I can buy them in packs of 12 to reduce costs.
All in all, I'm very happy with this project. Since finishing it, I have been able to consistently get the PM2.5 levels in my apartment down to zero and significantly reduce the time it takes to recover from a spike caused by cooking food.
I certainly could have cut the cost of this project in half by choosing a cheaper fan, like the box fans used in the reference Corsi-Rosenthal instructions, but I decided to spend more for a more quiet and reliable option.
Here are the STLs I used for this project. I certainly don't recommend just printing them as-is, since I am using the 12" x 12⅞" x ¾"5 custom air filters from my HVAC and you should probably use something more standard.
If you use these files as inspiration, your goal should be to make a box that is 16" wide, to fit the AC Infinity fan comfortably. I printed the "beams" in PETG at 100% infill and the feet in TPU 95:
The next step in this project is to automate the fan speed based on the PM2.5 levels in my apartment. At the moment, I manage this manually and it is becoming a chore.
This should be relatively easy to do with a Raspberry Pi Pico board, since AC Infinity sells a USB-C to Molex adapter for the fan.
This was with my pretty good range hood running at a reasonable level. Without it, I've seen PM2.5 levels spike as much as 250 from cooking alone. ↩
To be clear, this spike was not the result of me burning the hell out of a piece of meat or something like that. ↩
The HVAC either runs in manual "low | high" mode, or on a timed "20min ON | 40min OFF" loop that can be tuned by fiddling with a hydrostat knob that triggers the "high" mode. This is pretty dumb and makes it so the HVAC runs even when the apartment is empty or doesn't run enough to keep CO2 levels low when multiple people are there. A future project of mine will be to hack the controls to tie them into my air quality monitoring and trigger the HVAC based on CO2 levels. ↩
I'm also working on another HVAC hack to fix this. ↩
Sold, of course, as as 1" thick filters... ↩
10 November, 2026 09:00PM by Louis-Philippe Véronneau
I recently discovered some vulnerabilities in C-Kermit, one dating back to 1984. I tried to do the reasonable thing: create advisories with CVEs.
That turns out to be pretty difficult for a small independent project.
Large projects have a way to self-assign CVE IDs. They are their own CVE Numbering Authority (CNA). There is a massive list of CNAs. Just looking at the first page of results, I see everyone from Airbus to 9front (the niche Plan 9 OS). The OpenKermit project is not a CNA.
If you’re a CNA, you can create and publish CVEs on your schedule. There is apparently no external review process. You can wait for months, or publish immediately.
If you’re not a CNA, you have to find someone that is. The general ones that are CNAs appear to be Github and MITRE.
Since C-Kermit is hosted on Github, I thought I would go that route. I followed the documented procedure: created Github security advisories for C-Kermit, then clicked the request CVE button for each. The documentation states they will typically review within 72 hours.
It’s been a week and a half and no sign of a review yet. Apparently the real review time is more than a month.
The other option for projects without a CNA is via MITRE. You have to use a strange and often broken web form, logging in with either Google or Gitlab. (It seems to be broken on Firefox). Then you submit your request and wait.
How long do you wait on MITRE? It seems it could be anywhere from a day to several months.
The first CVE I obtained for C-Kermit was CVE-2025-68920. At the time, I had not yet started the OpenKermit project. That issue was found and fixed in the context of my work maintaining C-Kermit for Debian, and Debian is a CNA.
These were discovered while wearing my “upstream C-Kermit maintainer” hat. I’m sure I could ask Debian for CVEs again, but that seems a bit cheating; not everyone that maintains a FLOSS project will have connections with a distro like I do.
There are a lot of components of a modern OS and Internet ecosystem that are small projects without a large institution behind them.
This bias towards large organizations when it comes to communicating security problems benefits nobody. It doesn’t benefit users, and only serves to discourage timely communication. Not everyone is as persistent as I am, and when it is made so difficult to make announcements — which seem to go into a giant black hole — it’s easy to say, “why bother?”
By Microsoft’s own admission, they are under-funding their CVE process on Github (which may also be poorly-designed). They blame it on increasing load due to LLMs — a problem they helped create and predicted! Having a fiction about being able to communicate a security issue in a reasonable time is worse than not offering the path at all.
Linux was once a student’s experiment. Let’s not pretend that quality only matters from large projects.
10 November, 2026 01:42PM by John Goerzen

Debian's Cloud Images for various public cloud platforms and VM environments are built using a tool called debian-cloud-images, an in-house utility developed and maintained by the Debian Cloud Team.
The debian-cloud-images tooling uses FAI (Fully Automatic Installation) to create custom VM images for public clouds like GCP, Azure, and AWS, along with the genericcloud class. I wanted to convert this into a fully declarative, mkosi-based image build where the entire image is described using INI-format configuration files, with only a few post-installation scripts to handle final customizations.
I've been working with various image customization formats for a long time. In my previous company, I used to build customized industrial PC distributions based purely on Debian using multistrap and a bunch of shell scripts to stitch together raw image creation, bootloader installation, etc. I've also done custom installs using debootstrap on my own laptop with systemd-boot as the bootloader, but that was mostly hand-crafted and not automated. Once I came across mkosi, I was impressed by how a single utility can do everything and churn out a fully usable image without extra glue scripts for partitioning and image creation. You still need a few scripts to finalize some parts of the installation (via postinst hooks), but those are very minimal.
So I decided: why not convert debian-cloud-images into mkosi's declarative format with a few architectural changes? My requirements were:
Btrfs as the root filesystem: Partly because I like it, but primarily for the ability to use transparent compression (zstd:1), subvolumes, and snapshots for atomic rollbacks when things go wrong.
systemd-boot and Unified Kernel Images (UKI): Primarily because systemd-boot is clean and minimal—exactly what a modern bootloader should be. Combining it with UKIs and UEFI Secure Boot is bliss compared to the complexity of the GRUB2 world.
Note: This intentionally drops legacy BIOS (MBR/CSM) partitioning support in favor of pure UEFI. Modern cloud platforms (AWS Nitro, Azure Gen2, GCP) support UEFI natively, and dropping BIOS allows shedding significant legacy bootloader baggage—though it does make these images unsuitable for older, non-UEFI hypervisors.
Of course, the initial heavy lifting was done mostly using Antigravity (agy), along with debugging, tuning, and cleanup from my side. I pointed agy to a local copy of debian-cloud-images and laid out my requirements: preserve parity with the original packages and configurations, while enabling selective builds for each cloud via modular profiles. The resulting specification is documented here.
The repository also includes a verification script that audits functional parity against official images produced by debian-cloud-images (verifying packages, APT deb822 sources, and systemd services, while accounting for the switch to Btrfs and systemd-boot). Initial verification was performed for all Trixie profiles, and the parity report is published here.
I've also booted the genericcloud profile image under UEFI in a local VM to verify live bootability, bootctl status, network connectivity, and APT repository setup. This completes Phase 1 of the implementation. The remaining phases outlined in the specification include:
Another advantage of this setup is that the same tooling can build images for physical laptops and bare-metal servers. For example, in an earlier post, I walked through live-booting with debootstrap and manually configuring systemd-boot for a custom UEFI installation. With mkosi, I can simply generate a customized image locally with UKIs ready to go, live-boot the target machine, and write the image directly to the root disk.
This experiment is an exploration of the power of mkosi; I haven't discussed adoption with the Debian Cloud Team yet. For now, this will continue as my pet project. While I won't be hosting pre-built binary images, anyone interested is welcome to clone the repository and build the images locally.
I will probably take some more time before tackling dm-verity images, as I want to understand the nuances thoroughly before experimenting with them. Until then, happy hacking! Please report any issues or suggestions on GitHub.
10 November, 2026 07:00AM by copyninja
Here’s my monthly but brief update about the activities I’ve done in the FOSS world.

Whilst I didn’t have much time, here are still a few things that I worked on:
seeded-in-ubuntu no longer crashes when distro-info-data is outdated.
I joined Canonical to work on Ubuntu full-time back in February 2021.
<linux/rose.h>, so ROSE support has to go: (MP).
This month I have worked 3.50 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:
png_read_end() after incomplete zTXt, iTXt, or iCCP decompression (CVE-2026-46675).
Until next time.
:wq for today.
In previous articles, I explained how the Linux kernel implements IPv4 and IPv6 routing tables, and I showed the performance improvement of route lookups from Linux 2.6.32 to 4.16 for IPv4—including the impact of the Meltdown and Spectre mitigations—as well as from Linux 2.6.39 to 4.18 for IPv6. This article updates the numbers through Linux 7.3 and investigates the perpetrator responsible for the performance regressions! 🕵️♂️
I ran the following benchmarks on an AMD EPYC 8024P, a Zen 4c CPU, rented from Scaleway, running at 2.4 GHz with CPU boost disabled. I compiled the kernels with GCC 10.2: this version can compile older kernels as well as the current ones.

I tested four scenarios:
In Linux 4.15, Wei Wang improved the lookup performance by replacing the read-write lock with an RCU and a spinlock in commit 66f5d6ce53e6. In Linux 4.18, David Ahern improved the data structures used by route lookup. In Linux 5.9, Brian Vazquez removed expensive indirect calls in commit 55cced4f813b.
The major 200 ns regression introduced in Linux 6.5 wiped out all these
improvements. This version implements a mitigation for "Speculative Return
Stack Overflow," a vulnerability affecting AMD processors, in commit
fb3bd914b3ec. This mitigation adds about 20 cycles on each function return.
It was backported to older kernels (5.10, 5.15, 6.1, and 6.4). To keep the
results legible, I disabled the mitigation for these versions with
spec_rstack_overflow=off on the kernel command-line.
You can check the vulnerabilities impacting your CPU and their mitigations with
lscpu. Some mitigations may depend on the microcode or on the
firmware.1
$ lscpu | grep '^Vuln'
Vulnerability Gather data sampling:      Not affected
Vulnerability Indirect target selection: Not affected
Vulnerability Itlb multihit:             Not affected
Vulnerability L1tf:                      Not affected
Vulnerability Mds:                       Not affected
Vulnerability Meltdown:                  Not affected
Vulnerability Mmio stale data:           Not affected
Vulnerability Reg file data sampling:    Not affected
Vulnerability Retbleed:                  Not affected
Vulnerability Spec rstack overflow:      Mitigation; Safe RET
Vulnerability Spec store bypass:         Mitigation; Speculative Store Bypass disabled via prctl
Vulnerability Spectre v1:                Mitigation; usercopy/swapgs barriers and __user pointer sanitization
Vulnerability Spectre v2:                Mitigation; Retpolines; IBPB conditional; IBRS_FW; STIBP always-on; RSB filling; PBRSB-eIBRS Not affected; BHI Not affected
Vulnerability Srbds:                     Not affected
Vulnerability Tsa:                       Vulnerable: Clear CPU buffers attempted, no microcode
Vulnerability Tsx async abort:           Not affected
Vulnerability Vmscape:                   Mitigation; IBPB before exit to userspace

I tested three scenarios:
The 30 ns impact of the mitigation for SRSO in Linux 6.5 is smaller than for IPv6 because IPv4 route lookups traverse fewer functions: around 4 function calls for IPv4 compared to 25 for IPv6.
In Linux 5.11, I introduced a regression in commit c0c5a60f0f13 after
fixing the behavior of net.ipv4.conf.all.ignore_routes_with_linkdown!2
As a result, the ip_ignore_linkdown() function spends
around 5 additional cycles to return a result as it needs to follow three
additional pointers. fib_lookup() eventually calls it in the
following code:
if (ip_ignore_linkdown(nhc->nhc_dev) &&
    nhc->nhc_flags & RTNH_F_LINKDOWN &&
    !(fib_flags & FIB_LOOKUP_IGNORE_LINKSTATE))
    return false;
If we reorder the conditions, we avoid calling ip_ignore_linkdown() for the
most common case where the link isn't down:
if (nhc->nhc_flags & RTNH_F_LINKDOWN &&
    !(fib_flags & FIB_LOOKUP_IGNORE_LINKSTATE) &&
    ip_ignore_linkdown(nhc->nhc_dev))
    return false;
Here's the distribution of lookup times before applying the patch on top of net-next:3
min=128 max=4657 count=994104 95th=134 90th=133 50th=132 mad=0
    value │                         ┊                            count
      128 │                                                        120
      129 │                                                       2232
      130 │▒                                                     25224
      131 │▒▒▒▒▒▒▒▒▒▒▒▒▒░                                       264264
      132 │▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒░░░░░░░░░░░░░░░             516480
      133 │▒▒▒▒▒▒░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░      126864
      134 │▒░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░      21624
The lighter shade depicts the cumulative distribution function. After applying the patch, the median improved from 132 to 126 cycles:4
min=124 max=208839 count=994104 95th=128 90th=127 50th=126 mad=0
    value │                         ┊                            count
      124 │                                                        576
      125 │▒▒                                                    49440
      126 │▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒▒░░                      584904
      127 │▒▒▒▒▒▒▒▒▒▒▒▒▒▒░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░       284592
      128 │▒▒░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░░      45288
To reduce the impact of mitigations, you can disable all of them with
mitigations=off, disable only a specific one like with
spec_rstack_overflow=off, or protect against only some attack vectors with
mitigations=auto,no_user_kernel, starting from Linux 6.17.
The impact is also quite different depending on the CPU. For example, on a Xeon W-2295, an Intel desktop CPU from 2020, the impact of the mitigations is only a few cycles for IPv4, and less than 3% for IPv6. The main contributor is the mitigation for the Indirect Target Selection vulnerability, which is fixed since the Sapphire Rapids architecture.
If we set aside the regressions introduced by the mitigations against CPU attacks, the performance of IPv4 is declining slowly over time while IPv6 has improved in the past and is currently stable. If routing performance is important, you have several options: choose a different CPU like an AMD Zen 5 CPU, a fourth generation Xeon CPU, or maybe an ARM Neoverse V2; disable some or all the mitigations; bypass routing with XDP/eBPF;5 or offload routing to the network card.
Note
Maytham Alsudany reviewed a first draft of this article. Any errors are still mine!
The microcode was out of date on my machine as I forgot to install the
amd64-microcode package. As it only impacts TSA, our benchmark is
unaffected. Spectre v2 mitigation did not enable automatic IBRS, because
of SEV-SNP being enabled in the firmware. With automatic IBRS, the
impact of SRSO should be smaller. ↩
Despite ipvX in its title, the commit only changes the behavior of the
IPv4 code. The IPv6 version overwrites the value of each device in
addrconf_fixup_linkdown(). ↩
Linux 7.5 will be the first stable release including this fix. ↩
At 2.4 GHz, one cycle is about 0.42 ns. ↩
This requires avoiding bpf_fib_lookup(), which relies on
the same kernel lookup. ↩
09 November, 2026 08:07PM by Vincent Bernat
This was my hundred-forty-eighth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian.
During my allocated time I uploaded or worked on:
Besides doing these uploads, I reviewed the libssh upload (DLA-4844-1) and helped a bit in the background of the php uploads. Last but not least I spend some time on security-master to assist others (especially the kernel team) with uploads to Bookworm and Bullseye.
This month I uploaded a new upstream version or a bugfix version of:
This work is generously funded by Freexian!
This month I uploaded a new package vendor-ubuntu-touch to be able to build packages differently in an UbuntuTouch environment. I am curious when it will leave NEW. I also tried to finish two new applications.
This work has been generously funded by Fre(i)e Software GmbH!
This month I uploaded a new upstream version or a bugfix version of:
Unfortunately I had no time to work in this category this month.
This month I uploaded a new upstream version or a bugfix version of:
This month I uploaded a new upstream version of:
Due to different reasons I started to tidy up the list of packages I maintain. Some packages have been removed, some packages lost myself as uploader and some packages have been orphaned. The number of orphaned packages is about 1100 now, so maybe you can find one to adopt.
09 November, 2026 03:48PM by alteholz
The diffoscope maintainers are pleased to announce the release of diffoscope
version 338. This version includes the following changes:
[ Chris Lamb ]
* Binutils no longer shows the top-level directory; update expected test output.
  (Closes: #1151752)
You find out more by visiting the project homepage.
For some time now I’ve been looking for a way of keeping projects I’m working on in a separate VM without much setup. There are numerous solutions to do this kind of thing using namespaces (various container technologies, firejail, flatpak, bubblewrap, …) but I wanted something that uses real virtualization. I recently stumbled upon incus and it seemed like it could be a solution to my problem. Incus is a manager for both containers and virtual machines. It is possible to create VM images that can be used as templates, meaning that other machines can then be based on them on creation. Virtual machines can be configured using “profiles”.
For my use case, I have created a profile that defines how my template image should look like. In this profile I use cloud-init to configure the template machine on startup:
config:
  cloud-init.user-data: |
    #cloud-config
    apt:
      conf: |
        APT {
          Install-Recommends 0;
        }
    package_update: true
    package_upgrade: true
    package_reboot_if_required: true
    packages:
      - file
      - man-db
      - bat
      - eza
      - git
      - git-delta
      - neovim
      - zsh
      - tmux
      - curl
      - ncurses-term
      - hx
      - nix-bin
      - nix-setup-systemd
      - rustup
      - npm
      - podman
    users:
      - name: user
        lock_passwd: false
        # mkpasswd 'incus password'
        hashed_passwd: $y$j9T$p9XBP4Ox3SBUnyu.sqv5m1$f1rxcPJyVs05w./dZvIzu6.4dVWBvzu99nMBZRNlamD
        groups: sudo, nix-users
        shell: /usr/bin/zsh
        uid: 1000
    write_files:
      - path: /home/user/.config/nix/nix.conf
        content: |
          experimental-features = nix-command flakes
        permissions: 0600
      - path: /home/user/.zshrc.local
        content: |
          export PATH="$PATH:$HOME/.nix-profile/bin"
        permissions: 0600
    runcmd:
      - [curl, -sSfL, -o, /home/user/.tmux.conf, https://grml.org/console/tmux.conf]
      - [curl, -sSfL, -o, /home/user/.vimrc, https://grml.org/console/vimrc]
      - [curl, -sSfL, -o, /home/user/.zshrc, https://grml.org/console/zshrc]
      - [chown, -R, user:user, /home/user/]
description: Base template for dev VMs
...
and I use a script to regenerate the template image when I want to adapt the config:
#!/bin/sh

#set -e
set -x

NAME=dev-vm-template

# adapt the profile before rebuilding the template image
incus profile edit cloud-dev-template
incus delete --force ${NAME} || true
incus create images:debian/13/cloud --vm --quiet --profile default --profile cloud-dev-template ${NAME}
incus start ${NAME}
incus wait ${NAME} agent
incus exec ${NAME} -- cloud-init status --wait || true
incus stop ${NAME}
incus publish --alias cloud-dev-template --reuse ${NAME}
This script uses the debian/13/cloud image together with my
cloud-dev-template profile to set up a machine, configure it using
cloud-init and store the result as an image called cloud-dev-template.
To use this setup, I created a small python tool called
inker that talks to the incus REST
API. Using inker create creates a new VM based on my template. Using inker attach attaches
the current working directory to a VM as a readonly mount. It is possible to
combine those commands like inker create | inker attach to do those two steps
in one command. inker login logs into the VM that has the current directory
attached. This way I can create VMs that are connected to directories on my
filesystem.
I am currently playing around with this setup, but I think this could help me
to have a throwaway development machine, similar to dev
containers. I’m not sure yet how happy I am with
incus, though. I was also looking at systemd-vmspawn, but there are still
some features missing that I would need. But I might rewrite inker at some
point to use a different backend.

A new release of prrd arrived at CRAN today, and has already been built for r2u and on r-universe. The prrd package facilitates the parallel running [of] reverse dependency [checks] when preparing R packages. It is used extensively for releases I make of Rcpp, RcppArmadillo, RcppEigen, BH, and others.

The key idea of prrd is simple, and described in some more detail on its webpage and its GitHub repo. Reverse dependency checks are an important part of package development that is easily done in a (serial) loop. But these checks are also generally embarassingly parallel as there is no or little interdependency between them (besides maybe shared build depedencies). See the (somewhat dated) screenshot (running six parallel workers, arranged in a split byobu session).
This release updates internals to allow for greater concurrency. SQLite is used as the backend, both
for the job queue (managed via the liteq package) as
well as for storing actual reverse-dependency test results. It is
well-known that SQLite copes quite
well with multiple readers. Multiple concurrent
writers are more challenging. We tended to get by via
BEGIN EXCLUSIVE pragma use, but still get occassional issue
even at a somewhat moderate concurrency levels. After some back and
forth and trying a few approaches, more recently we established one
first solution relying on very explicity (OS-level, filesystem-based)
locking via package filelock. That
worked.
We mentioned this in an
old liteq issue that had circled around the same
question with a number of posts over the years, but no resolution. This
comment seemingly awoke Gábor, and he nailed this
years-open issue with a fine pull request deploying
BEGIN IMMEDIATE and well as a loop around
tryCatch to not immediately fail. I borrowed/ported that
approach to prrd and we now
have a second solution (and no longer need filelock). On a
somewhat better server with enough cores and memory, I am now running
eighteen concurrent workers—watched via three multi-pane byobu windows. Works like a charm without
issues. At last! A big thanks to Gábor for finding another
solution, and especially that only relies on SQLite.
The release is summarised in the NEWS entry:
Changes in prrd version 0.1.0 (2026-11-07)
Concurrent operations are now supported via updated sqlite semantics borrowed with appreciation from liteq
This follows an interim solution relying on filelock use; however this later package is not needed so no increase in dependencies
Courtesy of my CRANberries, there is also a diffstat report for this release.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
Half way through the day:
A morning of technical talks:
Vock - Instrumenting, kernel coverage and process tracing
Rebuilding the archive on your desktop
An overview of Secure Boot
An excellent lunch - with thanks to Liv and her Arm catering staff
Three lightning talks - two without slides :)
Excellent day so far :)
07 November, 2026 02:18PM by Andrew Cater (noreply@blogger.com)
There is a new project coming to Open Source Software land these days: OpenAGPS. It is not yet 100% functional, but we are working on it. It is not fully operational, yet, but we are on it.
Let me introduce OpenAGPS to you...
The domain of assisted geo location services has been left to a few big tech providers. When using GPS on mobile devices, most of us send info on our approximate device location (based on cell tower IDs seen by our devices around us) mostly to Google's SUPL service in order to facilitate a faster GNSS/GPS lock on the satellites flying above us.
Without assistance, retrieving a GNSS/GPS lock on sufficient satellites includes "finding" those satellites and once found retrieving data (in bytes/sec) from them. In some regions, this leads to waiting periods of up to 45 minutes, before a mobile devices has gained a lock on sufficient satellites (3 or more).
In Assisted-GNSS/GPS, "other" information (such as cell tower IDs) gets used to estimate what GNSS/GPS satellites are currently passing over one's location. With AGPS, the mobile devices retrieve information via a so-called SUPL server, containing two details: a list of potential satellites above and their dataframes. Esp. providing those dataframes over the device's internet connection (and not via the GNSS/GPS receiver downloading it from the satellite itself) speeds up the lock-on process of the mobile tremendously (several seconds to a few minutes).
However, for this mechanism to work, your device will share your IMSI (although not needed for AGPS), a list of cell towers around you and their signal strengths with the provider of the SUPL service, revealing your approximate position. In total, this allows SUPL providers to re-identify each mobile device and create motion profiles of each such device (and its owner). If the SUPL service is hosted by one main provider (i.e. Google SUPL), there is a lot of valuable information available to them for free that they can commercialize.
Currently, there is only one mitigation method available to hide one's location info from the SUPL server(s) at e.g. Google: using a SUPL proxy server implementation (available as OSS, provided by and used in e.g. GrapheneOS). A SUPL proxy still depends on the big tech service provider(s) for SUPL as it merely proxies SUPL requests from mobile devices through to the proprietary SUPL services, at e.g. Google, but the mobile device is being camouflaged behind the SUPL proxy in use.
OpenAGPS, on the contrary, will be a fully independent implementation from proprietary service providers, and it will refrain from collecting and commercializing end users’ data. It will be driven by individuals of the OpenAGPS community. There will likely be one central service that the OpenAGPS project plans to host and operate (the Porygon frontend/backend, OpenAGPS's GNSS Almanach service), but except from that SUPL servers can be self-hosted by individuals, companys or other communities. The requesting mobile devices' IDs will be hidden from the Porygon server (like with existing SUPL proxy implementations), so that the only centrally operated component (the Porygon Almanach server) does not know who is requesting what geo position information (and thus cannot collect such data, neither derive info about where requesting devices are located).
In addition, with a large OpenAGPS community, it is imaginable (in theory) that there will also be multiple central Almanach servers available on the internet (with parallel networks of base stations attached to each GNSS Almanach server).
Checkout the OpenAGPS architecture schematics and our website/documentation to learn more.
The OpenAGPS project is not simply a software that admins/users can install, it needs kind of a huge and global community to operate/host/house its base station network.
The challenge with providing a community-driven AGPS service on the internet is that up-to-date (real-time!) GNSS/GPS satellite position data is not available for free download. Almanach data can be obtained per region from various organisations, but then their datasets are often days to weeks old, thus too outdated. GNSS/GPS satellites are not geo-stationary, they circulate around the planet. Their position is dependent on the current date-time. A globally spanning network of GNSS/GPS base stations will do the trick here. We will need a community that harvests the needed satellite data in real time and makes it available through the Porygon Almanach server to all OpenAGPS users.
The OpenAGPS project will depend on at least one community member every ~40-50 km² to operate a so-called OpenAGPS base station: These base stations are stationary, need to run 24/7, and they will harvest GNSS/GPS statellite data information from the satellites above in real-time and share this data with the (central) Porygon server, continuously. The Porygon server will create a timestamp-dependent "map" of all seen satellites and extrapolate locations between base stations' Almanach data updates.
To make OpenAGPS a success, we need volunteers who are willing to host (actually: house) an OpenAGPS base station at their home or work place (or both). Users will only be able to use their self-hosted OpenAGPS SUPL server with their mobile devices (instead of e.g. Google SUPL), if we manage to establish sufficient coverage with those base stations in the area of interest, so that the OpenAGPS Almanach will get populated with sufficient satellite position data.
If you'd like to host/house such a base station, please get in touch and check the docs.
If you realize that you have an interest in this project and would like to improve your level of digital sovereignty in your government, organization, at your home, etc. then consider sending financial support to the project. If you want to support us, please get in touch with Raoul Kramer at BetaBreak or Mike Gabriel at Fre(i)e Software GmbH. If you are a software developer and would like to contribute to OpenAGPS, also get in touch and let us meet at FOSDEM 2027.
A huge thanks to the NLnet Foundation for funding this project's bootstrap phase. Follow-up funding has been applied for, so please keep fingers crossed!
07 November, 2026 09:23AM by sunweaver

Recently, I’ve been noticing something on packaging around my house that I used to glance right past: raised Braille dots on a carton of medicine, and embossed markings on a container of body cream. I’ve always known what Braille looked like, but I never paid close attention to it. Now that I’m actively working on accessibility testing for the Debian Installer, I see it everywhere.
It made me reflect on how accessibility usually enters our consciousness. In tech, we’re taught about accessibility as a best practice when designing user interfaces or web apps. But realistically, you mostly see it implemented well in massive global software, like mobile operating systems or browsers like Firefox. You rarely see accessibility features integrated into local Nigerian physical products or everyday tech. Paying attention to these details made me realize how much care goes into making sure every person is considered, and how vital that mindset really is.
My recent work with Debian has been focused on automating tests for the Debian Installer’s accessibility features, specifically validating Braille display emulation.
I started out by manually testing following the official steps on the Debian Installer Accessibility Wiki. Once I understood the manual flow, the next goal was figuring out how to automate it inside openQA.
Initially, the idea was to initialize from the bootloader by adding parameters to the Grub (GRUB=”brltty=auto”)and it should start the installation with the braille visual. However, this didn’t work, the parameters never initiated the brttyl and it was a huge blocker going back and forth. Getting brltty to talk to the test runner in that environment would have required sweeping changes across the main Debian openQA instance configuration.
Instead of pushing for complex system-wide changes on the instance, we started looking for easier alternative approaches and noted the complicated ones, when we advance in the test.
We brainstormed streaming the display output directly to a dedicated file to capture and verify the Braille virtual display output. Ultimately, nested virtualization proved to be the most easiest path forward.
You can check out the implementation details and changes in the Merge Request
As part of this work, I joined the debian-accessibility mailing list to introduce what we were building and share our progress.
The responses were encouraging. I got some feedback and suggestions and the thread also created a discussion on how accessible the installation process currently feels for blind or visually impaired users, and where they also find issues. It served as a great reminder that test suites aren’t just about passing CI checks, they’re about serving actual people who rely on these systems every day.
06 November, 2026 08:25PM by Isoken Ibizugbe

We're at the Arm office in Cambridge for fun conversations and Debian hacking, as part of this year's mini-DebConf. Here's some geek pron... :-)
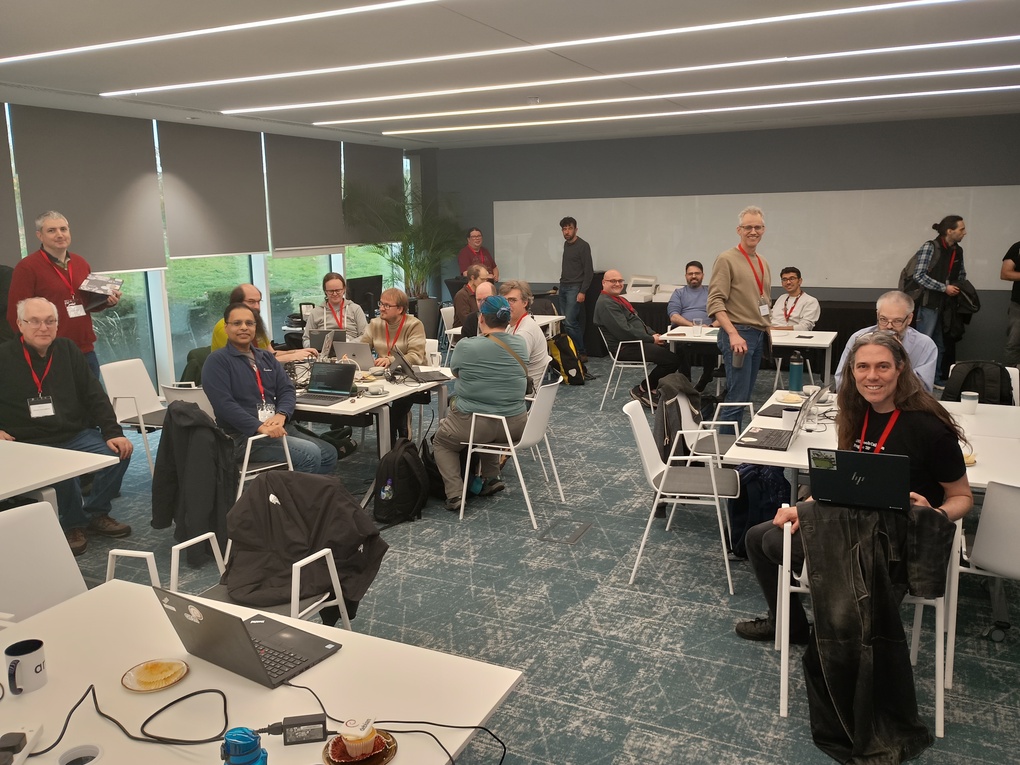
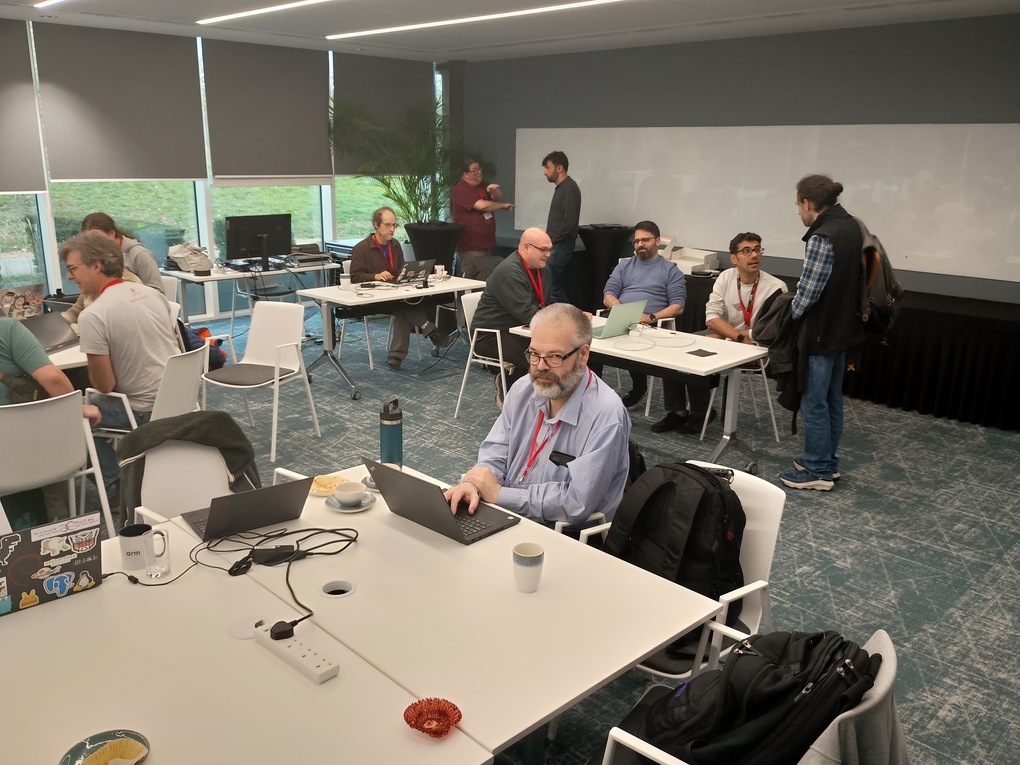
Massive thanks to the Arm folks for making us welcome: Steve Capper and especially Charlie Dixon for going above and beyond to set things up for us!
To optimize the performance metrics of this blog, I relied on Amazon CloudFront to serve the assets,1 and Route 53 for the geo-aware DNS2 to direct readers to the closest host serving the content. But Route 53 is expensive: US$0.50 per zone per month, US$0.70 per million geolocation queries, and US$0.75 per healthcheck per month, plus US$1 per month for the KMS key needed to sign zones with DNSSEC. When I discovered that Bunny DNS is almost free for up to 500 domains and features scriptable answers, I made the jump! Plus, it's a European company based in Slovenia.
Bunny.net started as BunnyCDN in 2015. They added IPv6
support in 2017. Switching was uneventful. I don't bring a custom domain: I
serve the content from the b-cdn.net domain. As I depend on content
negotiation to serve AVIF and WebP images, I configure the CDN to cache
each image format separately.
I disable logging to avoid collecting personal information. While the bunny.net GDPR page promises they anonymize data, it is unclear what CloudFront keeps in its own logs when logging is disabled.
The only downside of the bunny.net CDN offering is the lack of HTTP/3. I asked their support: two minutes later, they answered they are working on it but have no ETA to share.
Bunny.net introduced their DNS offering in 2022 and recently reduced its cost to almost zero. They support geographical routing, but a very cool feature is the scriptable DNS: it runs a piece of user-supplied JavaScript on each query to compute the answer.
I run seven small NixOS virtual machines to host this blog around the world: Paris, Nuremberg, Ashburn, Singapore, San Jose, São Paulo, and Sydney. Bunny's scriptable DNS lets me return the IP addresses of the two nearest servers. The browser falls back to the second server if the first one is down.
const servers = [
  {
    ipv4: "45.90.160.60",
    ipv6: "2a0c:8881:5:100::1",
    latitude: 48.88,
    longitude: 2.22,
  },
  /* […] */
  {
    ipv4: "139.180.162.114",
    ipv6: "2001:19f0:5800:1855:5400:6ff:fef0:4c0a",
    latitude: -33.87,
    longitude: 151.21,
  },
];
const families = { A: "ipv4", AAAA: "ipv6" };
const records = { A: ARecord, AAAA: AaaaRecord };

export default function handleQuery(query) {
  const type = String(query.request.queryType).toUpperCase();
  const family = families[type];
  if (!family) return [];
  // Get user location
  const location = query.request.geoLocation;
  // Build a list of candidates
  let candidates = servers.map(
    (s) => new Server(s[family], s.latitude, s.longitude, 100),
  );
  // Select the two closest alive servers
  const selected = [];
  while (selected.length < 2) {
    const server = RoutingEngine.getClosestServer(candidates, location, true);
    selected.push(server);
    candidates = candidates.filter((s) => s.ip !== server.ip);
  }
  // Return their IP addresses
  return selected.map((s) => new records[type](s.ip, 3600));
}
The above script relies on the
RoutingEngine.getClosestServer() helper, which returns the
closest alive3 server to the user.4 Thanks to Doggo, we can
check it works as expected, at least for A:5
$ doggo --gp-from="Amsterdam" A vincent.bernat.ch
LOCATION          NAME                TYPE  TTL    ADDRESS
Amsterdam, NL
                  vincent.bernat.ch.  A     3600s  45.90.160.60
                  vincent.bernat.ch.  A     3600s  116.203.18.48
$ doggo --gp-from="Texas" A vincent.bernat.ch
LOCATION          NAME                TYPE  TTL    ADDRESS
Houston (TX), US
                  vincent.bernat.ch.  A     3600s  5.161.44.145
                  vincent.bernat.ch.  A     3600s  149.28.219.155
The most annoying drawback of this method is that a user from Buenos Aires gets both São Paulo (1000 mi, 30 ms RTT) and Ashburn (5200 mi, 140 ms RTT). Most resolvers randomize the order, so the user may pull the web page from Ashburn. We could return only the nearest server—and swap the scripted record with the built-in geographic routing instead. But if the server becomes unavailable, the browser has no alternative until the DNS cache expires. It leaves a short window of unavailability, even with a short TTL.
The HTTPS DNS record, defined in RFC 9460, solves both the availability and the latency issues. Modern browsers query this record to get additional information to reach an HTTP server, including an alternative port and the application layer protocol—HTTP/2 or HTTP/3. Each record has a priority. We can ask browsers to contact the nearest server first and fall back to the next one if the first is unavailable:
vincent    HTTPS  1 first.geo  alpn="h3,h2"
vincent    HTTPS  2 second.geo alpn="h3,h2"
vincent    HTTPS  3 .          alpn="h3,h2"

; Bunny DNS must provide the two closest servers as "first.geo"
; and "second.geo" with geographic or latency routing.
first.geo  A      45.90.160.60
first.geo  AAAA   2a0c:8881:5:100::1
second.geo A      116.203.18.48
second.geo AAAA   2a01:4f8:1c0c:5eb5::1

vincent    A      45.90.160.60
vincent    A      116.203.18.48
vincent    AAAA   2a0c:8881:5:100::1
vincent    AAAA   2a01:4f8:1c0c:5eb5::1
This looks like the ideal solution! Unfortunately, Chrome ignores any record
whose target is not ., hence the last record at priority 3.
Moreover, unlike with a CNAME, Bunny DNS does not return the IP addresses for
first.geo and second.geo in the additional section. The resolver needs to
send a first request to get the HTTPS record, and a second to resolve
first.geo.
HTTPS records are still too new for this use case. Back to the drawing board! 📐
As a compromise, the script returns the two nearest servers if they are at a similar distance from the user. Otherwise, it returns only the nearest one with a lower TTL of 2 minutes.
export default function handleQuery(query) {
  const location = query.request.geoLocation;
  let candidates = servers.map(
    (s) => new Server(s.ipv4, s.latitude, s.longitude, 100),
  );

  // Select the two closest servers
  const selected = [];
  while (selected.length < 2) {
    const server = RoutingEngine.getClosestServer(candidates, location, true);
    selected.push(server);
    candidates = candidates.filter((s) => s.ip !== server.ip);
  }

  // Compute the distance to the user for each of them
  const [first, second] = selected.map((s) =>
    GeoDistance.calculate(s, location),
  );

  // If the second one is at twice the distance and at more than 1000 miles
  // from the first, return only the first one with a TTL of 2 minutes.
  if (second > 2 * first && second - first > 1000) {
    return [new ARecord(selected[0].ip, 120)];
  }

  // Otherwise, return both with a TTL of 1 hour.
  return selected.map((s) => new ARecord(s.ip, 3600));
}
We can check it with Doggo. From Chicago, we get only the Ashburn server with a TTL of 2 minutes, while from Mexico, we get both Ashburn and San Jose.
$ doggo --gp-from="Chicago" A vincent.bernat.ch
LOCATION          NAME                TYPE  TTL    ADDRESS
Chicago (IL), US
                  vincent.bernat.ch.  A     120s   5.161.44.145
$ doggo --gp-from="Mexico" A vincent.bernat.ch
LOCATION          NAME                TYPE  TTL    ADDRESS
Queretaro, MX
                  vincent.bernat.ch.  A     3600s  5.161.44.145
                  vincent.bernat.ch.  A     3600s  149.28.219.155
$ doggo --reverse 5.161.44.145 149.28.219.155
NAME                          TYPE  TTL    ADDRESS
145.44.161.5.in-addr.arpa.    PTR   7187s  web05.luffy.cx.
155.219.28.149.in-addr.arpa.  PTR   3600s  web07.luffy.cx.
Note
On the live page, the map below is interactive: point at a location to get the DNS answer, or disable servers to see how the answers change.

The complete code is a bit more complex. It works around
RoutingEngine.getClosestServer() supporting only IPv4, and it handles the case
where there are not enough alive servers to build an answer.
Bunny.net has a comprehensive Terraform provider. I leverage CDK Terrain to build the target state in TypeScript and OpenTofu to deploy it. Have a look at "Managing infrastructure with Terraform, CDKTF, and NixOS" for more details.6
Route 53 covered one additional use case of mine: serving acme.luffy.cx to
solve DNS-01 ACME challenges. Unlike Route 53, Bunny DNS cannot
restrict access to a single zone with a fine-grained access policy. As this
usage requires neither high availability nor low latency, I replaced Route 53
with Hickory, a memory-safe DNS server written in Rust. It supports
automatic DNSSEC signatures and dynamic updates. Its
configuration is simple:
[[zones]]
zone = "acme.luffy.cx"
zone_type = "Primary"

[zones.stores]
allow_update = true
type = "sqlite"
journal_path = "acme.luffy.cx.sqlite"
zone_path = "acme.luffy.cx.zone"

# Private key to sign the zone with DNSSEC. Generated with:
#  openssl genpkey -algorithm EC -pkeyopt ec_paramgen_curve:P-256
[[zones.keys]]
algorithm = "ECDSAP256SHA256"
key_path = "/etc/hickory-dns.acme.luffy.cx.pem"

# TSIG key to sign zone updates. Generated with:
#  openssl rand 32
[[zones.stores.tsig_keys]]
algorithm = "hmac-sha256"
key_file = "/etc/hickory-dns.acme.luffy.cx.update.acme.luffy.cx.tsig"
name = "update.acme.luffy.cx."
The provided zone file only seeds the database on first start. I delegate
DNS-01 challenges to this zone with CNAME records:
_acme-challenge          CNAME bernat.ch.acme.luffy.cx.
_acme-challenge.vincent  CNAME vincent.bernat.ch.acme.luffy.cx.
Lego, the ACME client I use to get certificates from Let's Encrypt, answers the DNS-01 challenge by pushing entries with the DNS UPDATE protocol.
Unfortunately, Bunny DNS cannot publish a DS record in a zone.7 I need one
to secure the acme.luffy.cx zone and certificate delivery. Therefore, I host
the luffy.cx zone on deSEC,8 a free DNS hosting service run by a
non-profit organization based in Berlin. I derive the DS record to publish in
luffy.cx from the DNSKEY record of acme.luffy.cx:
$ ZONE=acme.luffy.cx
$ dig @nsupdate.luffy.cx $ZONE DNSKEY +noall +answer \
>   | dnssec-dsfromkey -a SHA-256 -f - $ZONE
acme.luffy.cx. IN DS 55628 13 2 4946E7508F20E15F1B577A231104B029A1A82E04699A80CD46ADCE31227EE81F
Overall, I am quite happy with the switch to bunny.net. There are still a few
rough edges, like the inability to publish DS records, the lack of HTTP/3, and
the IPv4-only RoutingEngine.getClosestServer() helper. The bill went from US$5
per month to US$1. So far, performance is on par with AWS, but I
only finalized the current setup, including the server in Sydney, in late
October. I need a bit more time to gather more data, and I'll post a short update. 📈
Update (2026-11)
This post was briefly discussed on Hacker News and Lobsters.
I had been hosting media assets on CloudFront since 2011. ↩
Route 53 had served bernat.ch since December 2021. I didn't use healthchecks as
they were too expensive. I didn't host most of my zones there either, as queries
for haproxy.debian.net alone would have cost me around US$10 per month. ↩
A server is alive if it answers an ICMP ping. The bunny.net documentation gives more details about the checks. ↩
The user queries Bunny DNS through a resolver. Usually, either the resolver is close to the user, or it exposes the user's subnet through EDNS client subnet. ↩
Don't use this script as is: RoutingEngine.getClosestServer() only works
with IPv4. The final script works around this limitation. ↩
The article is a bit outdated. CDK Terrain replaces CDKTF, OpenTofu replaces Terraform, and I now use Colmena instead of NixOps. ↩
I contacted bunny.net support to ask when they will support publishing a
DS record and got an answer seven minutes later: they don't know. 😭
This is a bummer, as they support automatic CDS, a DNS record to advertise
a DS record to the parent zone. They handle one side of the delegation,
not the other.
I also reported a bug with the proof of non-existence, and they replied a day later with a detailed answer. ↩
Why not use deSEC for ACME challenges? You can limit its tokens to a single RRset. I could say I prefer to self-host, but the truth is I only discovered this while writing this article. ↩
06 November, 2026 01:29PM by Vincent Bernat
At Arm in Cambridge for two hackathon-type days before the main mini-Debconf on Saturday and Sunday. A roomful of people, mostly very quiet this morning but with people gradually arriving and greeting each other.
Just had an excellent lunch. Arm are excelling themselves, as ever. With particular thanks to Charlie Dixon who has arranged excellent facilities for us all and to Liv for the catering provision. Other old friends here have also helped as ever.
This sort of thing is ideal for cross-fertilization of experience, ideas - the side conversations where you realise that three people are converging to a consensus of discussion from three different starting points. It's fun and intensely interesting and it's the sort of thing that keeps me running Debian - and trusting the colleagues behind it because I've seen them here.
Face and name recognition is sometimes at least as valuable as rockstar coding and the social element and shared history keeps us pulling together.
06 November, 2026 12:15PM by Andrew Cater (noreply@blogger.com)
Another interesting morning so far. Lots of interesting side conversations (and, of course, people using IRC to talk to the person next to them as is traditional).
It's nice to hear somebody ask a question and be told, effectively "Oh, you need to talk to XX - they're sitting over there" or " I need to talk to someone about X, Y and Z - and they all resolve to you".
Especially noticeable in this room, perhaps, but it does point to the fact that many things in Debian ultimately resolve to one or two people. There are a lot of people each with multiple areas of expertise which overlap - and then a few individuals who are essential as points of reference for *everyone* else.
Thanks again to Arm for hosting us, for excellent food, coffee and facilities which make this _so much easier_ as a working environment for these days.
06 November, 2026 12:14PM by Andrew Cater (noreply@blogger.com)

06 November, 2026 10:48AM by Ben Hutchings

Your friendly keyring-maint Debian team received one of the weirdest
spam messages ever…
So, do we want to py to who-knows-whom for promoting the keyring-maint services in a verrrrrry-dark web search site?
First time I have to throw this stinky onion at you…
As a person that has lived in Kansas almost all my life, I have never seen such good political news for this state as we got this week. It is a stunning rebuke of fascism from across the country.
One of the many pieces of wisdom from mechanic Tom Magliozzi is this question: “Would you rather be right, or happy?” He often asked it in the context of somebody that had just won an argument.
This is my plea to all our progressive friends: remember that question, and keep it in mind carefully over the next 2 years. We can either build on this momentum for an even bigger victory in 2028, or we can start to lose this unique coalition.
Kansans spend our lives being misunderstood and forgotten.
Many of us, myself included, visit large cities regularly.
It is a more surprising event when someone from a large city drives down one of our dirt roads. The kind of road that leaves your car covered in mud when you drive your daughter to school. The kind of road that we drive on for 3 miles before we reach the nearest paved road.
Statisticians label Topeka, the capital of Kansas and city of 126,000 people, as rural.
The nearst town to me, 7 miles away, has a population of 600. In winter, many people here still leave their keys in their running, unlocked cars while they run into the grocery store. The person at the bank, the owner of the grocery store, the mechanic, the electricians, the builders, the people that run the local museum, all know my name and recognize me. Not because I’m famous locally, but because this is normal here. We are a community, a real one.
Yet I’ve lost long-time friends, especially from the west coast, because, while I’m progressive, I still talk to Republicans. They thought Republicans are so evil, they ought to be shunned and ostracized.
It probably doesn’t compute to a San Franciscan what it means to live in a county that went 80% for Trump one time. A county of about 10,000 people living in a space larger than Los Angeles, New York, and San Jose — combined. (Those cities have a combined population of about 13 million, living on the same amount of land as 10,000 people do out here.)
If I avoided talking to Republicans, it wouldn’t be them that would be isolated. It would be me.
Out here, many of us have lived with each other for generations. We may go on living with them for generations. If somebody’s car is stuck in the mud, the first person that comes by with a truck and a rope will probably pull them out. Nobody asks who you voted for. This is what you do for neighbors, because neighbors are humans, and next time it might be me that’s stuck in the mud.
I can be as incensed as anyone else about what the fascists are doing. I don’t have direct knowledge of how a lot of people vote. But I take a deep breath sometimes and remind myself: these are my neighbors. I’ve seen them go out of their way to be kind and generous with all walks of humanity. (Yes, even whatever groups you’re imaginging to argue with me about.)
This is part of how Adam Hamilton defeated Roger Marshal. The anti-Trump sentiment wasn’t enough on its own. Lifelong Republicans dissatisfied with how Trump handled things weren’t just going to vote for any Democrat. They needed someone that was safe. Someone that talked to them as humans. Someone that respected them.
Adam Hamilton went and shook hands with MAGA protestors at his events. He told them “I want to be your senator, too.”
This is how you win over the most strident of Republicans. Hamilton didn’t compromise his beliefs. He invited discussion about them.
I have already been seeing some progressives say things like, “Don’t cut them any slack. Remember how many times people voted for fascism! They need to still be ostracized.”
That, folks, is the way we lose. It is the wrong strategy everywhere. And it is especially culturally wrong in the close-knit communities — again, actual communities where people know each other and have for years — that make up the heartland.
Building relationships with people different than us is our best chance to build on this coalition. And, isn’t that what progressive values call for?
So, celebrate this victory. Clap for all the activists that made it happen.
And, before you set off to alienate your new and tentative allies, ask yourself:
“Would I rather be right? Or win again?”
05 November, 2026 06:19AM by John Goerzen
The diffoscope maintainers are pleased to announce the release of diffoscope
version 337. This version includes the following changes:
[ Chris Lamb ]
* Mark that the test_nupkg_compressed_files test requires the tlsh Python
* module. (Closes: #1151752)
You find out more by visiting the project homepage.

Hello, Planet Debian. My blog was added to the Planet today, so I think the polite thing is to introduce myself before you start finding my posts between yours.
I am Juan Manuel Méndez Rey, from Sevilla. In Debian I am mendezr, and on OFTC I am Vejeta. I have been using Linux since 1994 and Debian since 1998. For a long time that was all: a happy user, installing, breaking things, reading the mailing lists from the outside. I started contributing in October 2025, and last month I became a Debian Maintainer.
The way in was a friend. Back in 2019 Arturo Borrero Gonzalez filed RFP #943703 for Stremio, and for years he kept telling me I should pick it up. In September 2025 I finally listened and turned it into an ITP. It took longer than I like to admit, but Stremio is now in Debian, and I told that story here. A six year old RFP turned out to be a very good first package.
Somewhere along the way I discovered that what I enjoy most is bringing old software back.
The first one came from tille, who asked for help in #debian-tinytasks with xwpe, a Borland style programming editor for the terminal that nobody was looking after. I adopted it, and then I ended up as its upstream maintainer too. I fixed the old bugs and added LSP and DAP, so now an editor from 1993 can debug Go. It ships on several distributions, in Homebrew and on the BSDs. The canonical repo is on Codeberg, and the long version is in this post.
The second one is older and took much longer. Conquer is a Unix strategy game written by Ed Barlow and Adam Bryant in 1987, and I lost many hours of my youth to it. It never had a free licence. I first asked about it on debian-legal in October 2006, and I spent the next 20 years tracking down the authors, one email at a time. Today Conquer v4 and V5 are GPL-3.0. It is not packaged in Debian yet, that is the next step, but you can already play it in the browser.
CEF took me six months and brought me into the Chromium team, and these days I am mostly with the syft, trivy and grype security stack and with Scala 3 and sbt for Debian.
To Arturo, for the nudge. To dilinger, tille and tsimonq2, my DM advocates, for trusting me.
And if you can sponsor uploads for syft, trivy, grype or the Scala work, I would be very grateful. The details are on my wiki page.
You can find me there, as Vejeta on OFTC, or on Mastodon as @vejeta@mastodon.sdf.org. Nice to meet you all.
Last week, I received confirmation from my college's human resources department I was awarded tenure. If you ever worked in the academic world, you know how big of a deal this is.
In our fast moving and ever-increasingly unstable world, it is a pretty strange feeling to know you have a stable, well-paying job for the rest of your career. I am truly privileged to have an occupation I greatly enjoy.
Three cheers for another 30 years!
04 November, 2026 05:00AM by Louis-Philippe Véronneau
As with my last post on AI, let me open with a statement:
Just because most people hold AI a certain way, doesn’t mean that we always must, either now or in the future.
As I noted in that piece, and my shades of gray post, I am well aware — and agree with — the notion that a lot of frontier AI models have disturbing ethical concerns that we shouldn’t dismiss, including concentration of power and wealth, environmental concerns, unethical scraping and training, the financial bubble they seem to be creating, and more. The most poisonous of AI cheerleaders are accelerating enshittification while cutting quality all over the place. AI slop is also a real problem, which I’ll discuss in a bit.
Before I dive in, I need to mention that no AI assistance was used for writing this post, and I have been using em dashes — correctly — for years before LLMs did. Secondly, while popular discourse seems to use “AI” and “LLM” interchangeably, the AI field is much more broad and much more old than LLMs. I will, nonetheless, adopt the common “AI” jargon here, but be more specific when necessary to differentiate.
In The Reverse Centaur’s Guide to Life After AI by Cory Doctorow, he presented two ideas I particularly want to focus on here:
The two are related, in fact. Doctorow discussed how he never uses AI to write anything, but he sometimes uses it as an assistant to help him write. Is that contradictory? Not really. He gave this example: he remembered a quote from a podcast, which he wanted to cite and attribute correctly. But he couldn’t remember which podcast or who said it. So he fired up Whisper, an open-weight model you can download and run locally, even on meagre hardware. Whisper is a speech-to-text model. Doctorow ran likely podcast episodes (from the target range and set of podcasts he listens to) through the model, and at that point it was a regular search. He found the quote, then went back and listened to the episode at that time spot to verify its accuracy.
It would have taken so much time to do this without Whisper that he simply would not have done it otherwise. His writing was better because of AI. Not because AI wrote any words for him, but because it helped him find the right ideas and attributions. He didn’t even have to trust its transcription; it pointed him at the right place, and then he could transcribe with precision.
I too have used Whisper in much the same way. A little while back, I digitized many hours of old family audio recordings going back to the 1970s. Thanks to Whisper, which I ran locally primarily during hours of being fully solar-powered, I have a searchable index to these gems. A person I know recently asked me if I knew any way to transcribe some old family recordings he had. I told him I could run it through Whisper. It wouldn’t have great punctuation, but most of the words would be there. This meant a lot to him and his family; what I did in 2 minutes would have taken him many days (I presume he is not a fast typist as well.)
So we can start by naming: AI isn’t just chatbots, and AI can help even if it isn’t writing anything.
Doctorow goes on to ask the question: what happens after the AI bubble bursts? I do believe it will, as Ed Zitron has carefully documented for us for a long time now. The environmental damage done by frontier training and inference in the last few years will, of course, be done. But as he points out, we’ll be left with a plethora of surprisingly-capable open weight models, a community that has made significant strides running them on low-end devices (even phones), and a massive buildup of clean energy that hopefully will be finally able to offset some polluting energy once these heavy users drop off the grid.
So then what? Will the world just throw away the likes of Whisper and Gemma? Obviously not. Doctorow imagines, credibly, a situation in which individuals and universities tinker with locally-run models, iterating on them and improving them with the more traditional scale of resources available to individuals and universities. In other words, this future sounds a lot like the earlier days of Open Source.
As Ed Zitron has pointed out, the real costs of frontier AI have been hidden as these companies rack up fantastical losses. When the bubble bursts, the real costs of frontier AI are likely to be high enough that CEO’s won’t be able to ignore the poor ROI. But we’ll be left with these artifacts, these open-weight starting points, that people can use.
That brings me to my central thesis: a lot of anti-AI sentiment is focused on the real downsides of the hyped uses of AI, and fails to account for the more ethical advances being made now, and likely to come in the future.
Varying quality of AI use
We are all familiar with AI slop. I’ve seen it, and have an increasingly skeptical eye when I see “new” projects announced in even places as niche as a BBS community (where I see things like new terminal emulators announced, written in shockingly-poor nodejs, and such). I’ve seen documents that take many pages to say what amounts to nothing intelligble to a human, with perfect grammar. I’ve seen pull requests that have a description that amounts to several pages of slop. I’ve personally seen an AI agent do things like correctly detect passing an untrusted argument to a shell, then propose a broken quoting algorithm to fix it (rather than proper sanitization and exec() or, better yet, avoiding the call altogether.)
I’ve also seen AI tools very quickly and accurately identify bugs that had passed human review, even professional security reviews, for years. I’ve seen them bring more joy to some people’s jobs by handling the more drudgery parts of the jobs. One of my favorite podcasts, Oxide and Friends, had an episode called Engineering Rigor in the LLM age and credibly described ways in which careful use of LLMs can increase quality and safety. Yes, I said increase. (Oxide and Friends are not hype cheerleaders by any means; these are very serious people with solid technical chops, and I know some of them.)
What accounts for this disconnect?
We can point to many factors, but Doctorow asks a fundamental question: who is in charge? Is it the person or the computer? Does the AI service people, or do people service the AI?
In some of the most ridiculously AI-first companies, it is very clearly the latter. Mandates from CEOs to increase AI usage lead to perverse outcomes that sacrifice quality. The AI is in charge. I’ve never seen an AI be any good at design questions, and it’s no wonder than all these vibe-coded apps have the same generic feeling of crappiness.
But when the AI is used pragmatically as a junior research assistant, that’s a different approach. Its output is greeted skeptically, its actions distrusted, and it’s never asked to design something. These are the cases where I’ve seen it make a meaningful difference.
It’s not black-and-white
All this adds up to why I was opposed to the Debian proposals that would have banned LLM use. Those votes are hard to change. They would have left Debian in a vulnerable position of being unable to react to accurate security findings if they originated with an LLM, or left Debian unable to adopt ethical use of models.
It would be akin to saying “you should never buy a PC because Windows 11 is terrible.” I agree Windows 11 is terrible, but saying something like that is so dismissive of all those that have invested decades of their time in building something better.
So, I find AI hype to be uncredible and dangerous. I also find knee-jerk reactions to AI to be the same. They are actually a form of capitulation: they let the AI megacorps dictate the terms of the conversation to revolve around them.
Case study: Debian’s DFSG scanner
For a long time, my two biggest annoyances with Debian have been the difficulty of packaging Rust and Go packages with their long dependency trees, and how long it takes a new package to get reviewed. About a year ago, the latter process was set on a path to reform, and it has gotten dramatically better. It also cuts off a potential connection with someone that hasn’t yet heard of Linux. Some people may not jump from Windows 11 (or the ChatGPTs of the world) immediately, but pretending that it’s ChatGPT or nothing does a disservice to all those that are trying to do research etchically.
We should state at the outset that Debian takes compliance with the Debian Free Software Guidelines (DFSG) extremely seriously. Every new package gets a review, and these reviews often catch things that upstream repos and other distros don’t. One common example would be a package that has a stated copyright and license, but then includes files that bear a different copyright and license.
You can imagine reviewing packages at this level of detail isn’t a fun task for people, and it’s hard to find volunteers to do it. Perhaps the answer to this should be “Debian should stop caring so much more than everyone else”, and perhaps you’re right (and perhaps you aren’t).
In any case, the DFSG team that reviews this added what amounts to an LLM-backed license linter. Its job is to produce an initial assessment that the license statements documented in debian/copyright are correct, thorough, and in compliance with DFSG. This report was not taken to be authoritative, but was designed to help with some initial assessments.
There were some predictable reactions. People were angry that the DFSG team had added this tool without any communication about it (justifiably so, I’d say). Many were angry just because of LLM. People made assumptions about what kind of model it used, what kind of quality it would produce, how definitive it would be in the project.
It is worth noting here that Debian is uniquely decentralized. There is a central policy, but maintainers are free to maintain their packages how they like. They don’t have to use a standard location for a Git repo, or even use Git.
One person said essentially, “it’s fine for others to use whatever tool they want, but I shouldn’t have to be exposed to LLM slop.” The other perspective boiled down to, “why should they keep the reports secret? If you want to proactively fix things, or flag false positives, why not?”
As Andreas Tille wrote, “I have read the LLM reviews carefully, and in many cases their findings inspired additional commits to improve my packaging. In some cases, they even helped me catch mistakes that led me to reject an upload myself before human inspection.”
Joey Hess raises an interesting risk: that LLMs will remove the incentive for Debian to actually fix its cumbersome processes, by letting an LLM paper them over. I have seen this tendency in other contexts, both at work and at home, as well. It’s a real risk, especially if Debian doesn’t tackle the packaging problem for Rust and Go.
The Mastodon post that prompted me to write this began a chain of events that started with “Uploaders will be forced to address LLMs issues without human inspection.” I don’t believe that will be the case; it goes too far against the Debian ethos.
I encourage everyone to take a deep breath. We are all getting used to a shifting landscape. We will all make missteps, myself included. The issues are complicated, the picture isn’t black and white, and there is incredible hype around the ecosystem that can make finding nuance difficult.
Let’s be kind to each other, fellow humans.
But, I do not care if you are kind to Claude.
03 November, 2026 01:04AM by John Goerzen
Another new version of our still-new-ish package myman reached CRAN this morning, and has been built for r2u and on r-universe. The matching Python package has also been updated. The package offers twenty two hundred eighty four “My man …” posts by Kevin Kruse made on bsky during the summer of 2026. Each wave picked at one particular public persona. This package wrapse these up in the style of packages like fortunes or gaussfacts.
This release contains a new wave from October 31 to November 1 poking fun at Mike Johnson—just in time for the election.
> library(myman)
> set.seed(20261102)  # reproducible sampling
> myman(target="Mike Johnson")
My man looks like he used parental controls to block "Pimp My Ride".
     -- about Mike Johnson on 2026-11-01

>
So have a chuckle, and then go out and vote! The short NEWS entry for this release follows.
Changes in version 0.13.0 (2026-11-02)
- New wave thirteen (100 posts); total is now 2284 posts
Courtesy of my CRANberries, there is also a diffstat report for the most recent release. More information is available at the repository or the package page.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
After quite some time, I picked up debvulns again to implement what I mentioned in my previous post: exporting reboot required status and identifying services that need a restart. Additionally, I wanted to ensure kernel vulnerabilities are not marked as fixed unless the running kernel matches or exceeds the fixed version. Both features are now live in version 0.2.4 (intermediate release 0.2.3 only included the needrestart functionality).
When you update packages on a system, security fixes do not take effect until running processes actually use the updated binaries from disk. When an upgrade occurs, existing processes continue executing the older, vulnerable code loaded into memory, while only newly spawned instances pick up the fixed binary. The needrestart package in Debian exists specifically for this purpose. It can run in either report mode or action mode: report mode provides machine-readable output, while action mode automatically restarts affected services.
needrestart is a standalone utility that can run independently or hook into apt to run automatically after an upgrade. On desktop systems, it typically runs interactively with a TUI prompt; on headless servers, it can be set to take non-interactive default actions. In batch mode, it avoids restarting sensitive system components (such as dbus) to prevent destabilizing the session.
Integrating this into debvulns is not about replacing needrestart or debsecan, but rather bringing vulnerability and remediation state into a single, discoverable interface. debvulns aggregates these signals into a standard format—in this case, Prometheus metrics and tags that can be visualized in Grafana, monitored by alerting systems, or consumed downstream by automation tools.
Just as user-space daemons require a restart after patching, a patched kernel requires a system reboot into the new image before the vulnerability is truly mitigated. Previously, debvulns only verified whether the patched package version was installed on disk. If the deb package was installed, the CVE was marked as resolved, which creates a false sense of security while running the old kernel.
With this release, debvulns now checks the active running kernel release. A kernel vulnerability is considered resolved only when the system is running the fixed kernel version. Until a reboot happens, the system remains reported as vulnerable.
The updated dashboard reflects these changes below. It will need further polish, but key metrics and restart/reboot states are now visible:
These were the two pending functional areas I wanted to cover, and no further major features are planned for now. Next up will be reviewing the entire codebase to identify potential optimizations and remove any unnecessary complexity. I haven't done a full pass through the repository since the initial skeleton implementation, so testing edge cases and cleaning up the internals will be the main focus. This will likely take some time since I only hack on this during weekend downtime. Until then, happy hacking, give the new release a try, and file an issue if you run into bugs.
01 November, 2026 12:33PM by copyninja
To experiment with network stuff, I was using UML-based network labs. Many alternatives exist, like GNS3, Netkit, Marionnet or Cloonix. All of them are great viable solutions but I still prefer to stick to my minimal home-made solution with UML virtual machines. Here is why:
The use of UML had some drawbacks:
However, UML features HostFS, a filesystem providing access to any part of the host filesystem. This is the killer feature which allows me to not use any virtual disk image and to get access to my home directory right from the guest.
I discovered recently that QEMU provided 9P, a similar filesystem on top of VirtIO, the paravirtualized IO framework.
The setup of the lab is done with a single self-contained shell file. The layout is similar to what I have done with UML. I will only highlight here the most interesting steps.
My initial goal was to experiment with
Nicolas Dichtel’s IPv6 ECMP patch. Therefore, I needed to
configure a custom kernel. I have started from make defconfig,
removed everything that was not necessary, added what I needed for my
lab (mostly network stuff) and added the appropriate options for VirtIO
drivers:
CONFIG_NET_9P_VIRTIO=y
CONFIG_VIRTIO_BLK=y
CONFIG_VIRTIO_NET=y
CONFIG_VIRTIO_CONSOLE=y
CONFIG_HW_RANDOM_VIRTIO=y
CONFIG_VIRTIO=y
CONFIG_VIRTIO_RING=y
CONFIG_VIRTIO_PCI=y
CONFIG_VIRTIO_BALLOON=y
CONFIG_VIRTIO_MMIO=y
No modules. Grab the complete configuration if you want to have a look.
From here, you can start your kernel with the following command
($LINUX is the appropriate bzImage):
qemu-system-x86_64 \
  -m 256m \
  -display none \
  -nodefconfig -no-user-config -nodefaults \
  \
  -chardev stdio,id=charserial0,signal=off \
  -device isa-serial,chardev=charserial0,id=serial0 \
  \
  -chardev socket,id=con0,path=$TMP/vm-$name-console.pipe,server,nowait \
  -mon chardev=con0,mode=readline,default \
  \
  -kernel $LINUX \
  -append "init=/bin/sh console=ttyS0"
Since there is no disk to boot from, the kernel will panic when trying
to mount the root filesystem. QEMU is configured to not display video
output (-display none). A serial port is defined and uses stdio as
a backend.1 The kernel is configured to use this serial port
as a console (console=ttyS0). A VirtIO console could have been used
instead but it seems it is not possible to make it work early in the
boot process.
The QEMU monitor is setup to listen on a Unix socket. It is possible
to connect to it with socat UNIX:$TMP/vm-$name-console.pipe -.
Update (2012-10)
I was initially unable to mount the host filesystem as the root filesystem
for the guest directly by the kernel. In a comment, Josh
Triplett told me to use /dev/root as the mount
tag to solve this problem. I keep using an initrd in this post but the lab
on GitHub has been updated to not use one.
Here is how to build a small initial ramdisk:
# Setup initrd
setup_initrd() {
    info "Build initrd"
    DESTDIR=$TMP/initrd
    mkdir -p $DESTDIR

    # Setup busybox
    copy_exec $($WHICH busybox) /bin/busybox
    for applet in $(${DESTDIR}/bin/busybox --list); do
        ln -s busybox ${DESTDIR}/bin/${applet}
    done

    # Setup init
    cp $PROGNAME ${DESTDIR}/init

    cd "${DESTDIR}" && find . | \
       cpio --quiet -R 0:0 -o -H newc | \
       gzip > $TMP/initrd.gz
}
The copy_exec function is stolen from the initramfs-tools package
in Debian. It will ensure that the appropriate libraries are also
copied. Another solution would have been to use a static busybox.
The setup script is copied as /init in the initial ramdisk. It will
detect it has been invoked as such. If it were omitted, a shell would
be spawned instead. Remove the cp call if you want to experiment
manually.
The flag -initrd allows QEMU to use this initial ramdisk.
Let’s mount our root filesystem using 9P. This is quite easy. First QEMU needs to be configured to export the host filesystem to the guest:
qemu-system-x86_64 \
  ${PREVIOUS_ARGS} \
  -fsdev local,security_model=passthrough,id=fsdev-root,path=${ROOT},readonly \
  -device virtio-9p-pci,id=fs-root,fsdev=fsdev-root,mount_tag=rootshare
${ROOT} can either be / or any directory containing a complete
filesystem. Mounting it from the guest is quite easy:
mkdir -p /target/ro
mount -t 9p rootshare /target/ro -o trans=virtio,version=9p2000.u
You should find a complete root filesystem inside /target/ro. I have
used version=9p2000.u instead of version=9p2000.L because the
latter does not allow a program to mount() a host mount
point.2
Now, you have a read-only root filesystem (because you do not want to mess with your existing root filesystem and moreover, you did not run this lab as root, did you?). Let’s use a union filesystem. Debian comes with AUFS while Ubuntu and OpenWRT have migrated to overlayfs. I was previously using AUFS but got errors on some specific cases. It is still not clear which one will end up in the kernel. So, let’s try overlayfs.
I didn’t find any patchset ready to be applied on top of my kernel tree. I was working with David Miller’s net-next tree. Here is how I have applied the overlayfs patch on top of it:
$ git remote add torvalds git://git.kernel.org/pub/scm/linux/kernel/git/torvalds/linux-2.6.git
$ git fetch torvalds
$ git remote add overlayfs git://git.kernel.org/pub/scm/linux/kernel/git/mszeredi/vfs.git
$ git fetch overlayfs
$ git merge-base overlayfs.v15 v3.6
4cbe5a555fa58a79b6ecbb6c531b8bab0650778d
$ git checkout -b net-next+overlayfs
$ git cherry-pick 4cbe5a555fa58a79b6ecbb6c531b8bab0650778d..overlayfs.v15
Don’t forget to enable CONFIG_OVERLAYFS_FS in .config. Here is how
I configured the whole root filesystem:
info "Setup overlayfs"
mkdir /target
mkdir /target/ro
mkdir /target/rw
mkdir /target/overlay
# Version 9p2000.u allows one to access /dev, /sys and mount new
# partitions over them. This is not the case for 9p2000.L.
mount -t 9p        rootshare /target/ro      -o trans=virtio,version=9p2000.u
mount -t tmpfs     tmpfs     /target/rw      -o rw
mount -t overlayfs overlayfs /target/overlay -o lowerdir=/target/ro,upperdir=/target/rw
mount -n -t proc  proc /target/overlay/proc
mount -n -t sysfs sys  /target/overlay/sys

info "Mount home directory on /root"
mount -t 9p homeshare /target/overlay/root -o trans=virtio,version=9p2000.L,access=0,rw

info "Mount lab directory on /lab"
mkdir /target/overlay/lab
mount -t 9p labshare /target/overlay/lab -o trans=virtio,version=9p2000.L,access=0,rw

info "Chroot"
export STATE=1
cp "$PROGNAME" /target/overlay
exec chroot /target/overlay "$PROGNAME"
You have to export your ${HOME} and the lab directory from host:
qemu-system-x86_64 \
  ${PREVIOUS_ARGS} \
  -fsdev local,security_model=passthrough,id=fsdev-root,path=${ROOT},readonly \
  -device virtio-9p-pci,id=fs-root,fsdev=fsdev-root,mount_tag=rootshare \
  -fsdev local,security_model=none,id=fsdev-home,path=${HOME} \
  -device virtio-9p-pci,id=fs-home,fsdev=fsdev-home,mount_tag=homeshare \
  -fsdev local,security_model=none,id=fsdev-lab,path=$(dirname "$PROGNAME") \
  -device virtio-9p-pci,id=fs-lab,fsdev=fsdev-lab,mount_tag=labshare
You know what is missing from our network lab? Network setup. For each LAN that I will need, I spawn a VDE switch:
# Setup a VDE switch
setup_switch() {
    info "Setup switch $1"
    screen -t "sw-$1" \
        start-stop-daemon --make-pidfile --pidfile "$TMP/switch-$1.pid" \
        --start --startas $($WHICH vde_switch) -- \
        --sock "$TMP/switch-$1.sock"
    screen -X select 0
}
To attach an interface to the newly created LAN, I use:
mac=$(echo $name-$net | sha1sum | \
            awk '{print "52:54:" substr($1,0,2) ":" substr($1, 2, 2) ":" substr($1, 4, 2) ":" substr($1, 6, 2)}')
qemu-system-x86_64 \
  ${PREVIOUS_ARGS} \
  -net nic,model=virtio,macaddr=$mac,vlan=$net \
  -net vde,sock=$TMP/switch-$net.sock,vlan=$net
The use of a VDE switch allows me to run the lab as a non-root
user. It is possible to give Internet access to each VM, either by
using the -net user flag or using slirpvde on a special switch. I
prefer the latter solution since it will allow the VMs to speak to each
other.
This lab was mostly done to debug both the kernel and Quagga. Each of them can be debugged remotely.
While the kernel features KGDB, its own debugger, compatible with GDB, it is easier to use the remote GDB server built inside QEMU.
qemu-system-x86_64 \
  ${PREVIOUS_ARGS} \
  -gdb unix:$TMP/vm-$name-gdb.pipe,server,nowait
To connect to the remote GDB server from the host, first locate the
vmlinux file at the root of the source tree and run GDB on it. The
kernel has to be compiled with CONFIG_DEBUG_INFO=y to get the
appropriate debugging symbols. Then, use socat with the Unix socket
to attach to the remote debugger:
$ gdb vmlinux
GNU gdb (GDB) 7.4.1-debian
Reading symbols from /home/bernat/src/linux/vmlinux...done.
(gdb) target remote | socat UNIX:$TMP/vm-r1-gdb.pipe -
Remote debugging using | socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-gdb.pipe -
native_safe_halt () at /home/bernat/src/linux/arch/x86/include/asm/irqflags.h:50
50  }
(gdb)
You can now set breakpoints and resume the execution of the kernel.
It is easier to debug the kernel if optimizations are not
enabled. However, it is not possible to
disable them globally. You can however disable them
for some files. For example, to debug net/ipv6/route.c, add
CFLAGS_route.o = -O0 to net/ipv6/Makefile, remove
net/ipv6/route.o and type make.
To debug a program inside QEMU, you can just use gdb as usual. Your
$HOME directory is available and it should therefore be
straightforward. However, if you want to perform some remote
debugging, that’s quite easy. Add a new serial port to QEMU:
qemu-system-x86_64 \
  ${PREVIOUS_ARGS} \
  -chardev socket,id=charserial1,path=$TMP/vm-$name-serial.pipe,server,nowait \
  -device isa-serial,chardev=charserial1,id=serial1
Start gdbserver in the guest:
$ libtool execute gdbserver /dev/ttyS1 zebra/zebra
Process /root/code/orange/quagga/build/zebra/.libs/lt-zebra created; pid = 800
Remote debugging using /dev/ttyS1
And from the host, you can attach to the remote process:
$ libtool execute gdb zebra/zebra
GNU gdb (GDB) 7.4.1-debian
Reading symbols from /home/bernat/code/orange/quagga/build/zebra/.libs/lt-zebra...done.
(gdb) target remote | socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-serial.pipe -
Remote debugging using | socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-serial.pipe -
Reading symbols from /lib64/ld-linux-x86-64.so.2...(no debugging symbols found)...done.
Loaded symbols for /lib64/ld-linux-x86-64.so.2
0x00007ffff7dddaf0 in ?? () from /lib64/ld-linux-x86-64.so.2
(gdb)
For a demo, have a look at the following video:
stdio is configured such that signals are not
enabled. QEMU will not stop when receiving SIGINT. This is
important for the usage we want to have. ↩
Therefore, it is not possible to mount a fresh /proc
on top of the existing one. I have searched a bit but
did not find why. Any comments on this are welcome. ↩
01 November, 2026 09:57AM by Vincent Bernat
The orphaning of usbguard and usbguard-notifier is because I don’t use those
packages anymore. I rather spend my time on FOSS projects in areas I get
something out of. This is also due to a growing frustration with the Debian
community. The discussions on the mailing lists in the recent months lacked any
sense of social etiquette. The delusional conviction that certain tools improve
the work environment for EVERYONE took on religious overtones.
This is all the more troubling now that even central infrastructure is being drawn into this forced “blessing.” And it seems there is absolutely no awareness here of the boundary violations that are being normalized. Reminds me a bit of christian missionaries.
In the APIS project I finally merged the search app I wrote a couple of months ago. Based on the proof of concept for the HTMX autocomplete, I implemented an autocomplete that uses the search app for the results, therefore allowing to list search results of multiple content types. I released 0.68, 0.69, 0.70, 0.71 and 0.72 of the APIS framework. The 0.68 release changed the way we list the Django content types, leading to less database hits. In the 0.71 release I refactored the detail & edit views for generic models.
I was torn about whether I should go to this years congress, but in the end I decided to go again. I guess it will be something about the 20th time I’m attending.
In hydrology, a distributary is a channel that forks away from a river and flows on to the sea, the opposite of a tributary. Debian is the river much of the Linux world forks from, so for a release called forky, that is my proposal for its artwork: one river, many forks.
All generated by code. A small Python program grows the river by the rules of real deltas, and renders every wallpaper, login screen, boot splash and GRUB background from it, dark and light, at any resolution: the showcase offers 51 sizes to download, from phones to 8K.
It comes in eight colours, and with the palette editor you can fork your own: change any colour or option live in your browser, or roll random ones, then download the wallpaper or build the whole theme locally. Have a look at the showcase and at the proposal on the Debian wiki; the source is on Salsa and GitHub.
31 October, 2026 05:22PM by Samuel Henrique (samueloph)

I just released a new version of PyKCS11, a Python wrapper above the PKCS#11 API.
See PyKCS11 introduction or PyKCS11’s documentation.
The project is registered at Pypi: https://pypi.org/project/PyKCS11/
1.5.21 - October 2026, Ludovic Rousseau
getMechanismList(): do not return mechanism 0x1D (debug code
introduced by mistake in release 1.5.19)
build binary wheels for Python 3.15
31 October, 2026 01:20PM by Ludovic Rousseau
Artem wrote an interesting blog post about trying and failing to contain a LLM agent with VMs, they think this is bad but I think it’s great that more bugs are being discovered and could then be fixed [5]. I now want to try this sort of thing on replicas of my own systems!
404Media has an interesting article about the ways that “AI” agents are ruining the Internet [10].
31 October, 2026 01:07PM by etbe
I just released a new version of pyscard. PySCard is a Python module adding smart cards support (PC/SC) to Python.
The PySCard project is available from:
I removed the distribution from sourceforge. Use PyPI instead. On PyPI you wil get a red alert "Incomplete provenance" for the source code file pyscard-2.3.2.tar.gz. This is because I manually uploaded it using twine (as before). The next release will be uploaded to PyPI by a github action (as is already the case for the binary wheels).
No code change in this release.
I created a new release to ensure that the binary wheels for Python 3.14 and 3.15 were uploaded to PyPI. This is intended for systems that are difficult to use for rebuilding PySCard, particularly Windows.
add builds for Python 3.14 & 3.15
Minor changes
31 October, 2026 12:52PM by Ludovic Rousseau
In April I got my Furilabs FLX1s basically working [1].
Below is a post I wrote about the FLX1s before it broke at the start of September, there was a problem with the display controller and it would randomly go into a messed up mode that wasn’t readable but also changed a bit in relation to button presses etc so the phone was still working. Also I could ssh to the phone when it was in that state if it was on my home wifi.
It took almost 2 months to get a replacement phone but I now have that working and the new 14.1.0 OS release. So some of the below may be obsolete when it comes to the latest release but I decided to publish it anyway for history if nothing else.
One thing I had known about but not mentioned before is that the icon in the drop-down menu for the hotspot will often be gray (indicating hotspot-off) when it’s actually on. To address that I have to click on it (which then indicates that the hotspot is on) and then click on it again to turn it off.
Currently I have problems with QT6 applications that don’t run due to library issues and issues of missing GL support. I blogged about setting up my own container on my phone [2] which helped for some things but not for most things.
I have given up trying to get Tokodon working on the phone for the moment. Tokodon is a nice Mastodon client that would allow me to get notifications from Mastodon.
Apparently the Furilabs people are working on some issues related to this.
Bluetooth is currently a bit unreliable. When I turn on my car (Nissan LEAF) the phone usually either doesn’t connect or claims to be connected while not sending audio to the car. When it does connect my favourite music player (Lollypop) usually doesn’t display the album and track names. I’ve found that turning my car off and on again usually makes it connect properly.
I admit the possibility of my car not doing things correctly in this regard. But every Android phone I tried just worked, they would connect as soon as the car was turned on and correctly display track names. So if the car is doing things wrong and needs a software work around then Linux is at fault for not doing that – we can’t get tens of millions of cars and hundreds of millions of other weird devices fixed!
I also note that my Debian laptop and a friend’s Debian laptop also have problems connecting to my car. So it’s quite possible that Debian code is at fault (the FLX1s is running a modified version of Debian).
It currently appears to have no support for handset mode so I can’t answer phone calls through the car interface. But this is a lesser problem.
I plan to do more testing with Debian laptops and file some bug reports if I can find out enough useful information. My current knowledge of this is insufficient to create a useful bug report. I do have quite a few bluetooth headsets and test laptops so I plan to start by testing Debian and Ubuntu on all the combinations – last time I tested Ubuntu 24.04 on Dell laptops worked much better than Debian/Trixie on Thinkpads.
After a set of updates including the following Wifi hotspot seems to be working.
adaptation-furiphone-radon (1.3.0+git20260513192743.e94f2ec.forky.production) forky; urgency=medium

  * NetworkManager: sync hotspot channel/band with STA and restart on change
  * debian: depend on libhybris-utils and libgbinder-tools
  * startup: drop schedtune and add m4u debug log level
  * startup: enable glove and disable edge palm
  * device: drop flashlightd-scalable signatures

 -- Bardia Moshiri <bardia@furilabs.com>  Wed, 13 May 2026 15:27:43 -0400
Connecting the power cable now makes the phone immediately make the click sound and it starts charging while previously there was a 22 second delay. Once I get used to this I can avoid the problem of failing to plug it in firmly before going to bed and having it run flat overnight.
The following command will send a message via SMS.
dbus-send --system --print-reply --dest=org.ofono /ril_0 org.ofono.MessageManager.SendMessage string:"+61400000000" string:"this is the message"
Also the Librem5 Wiki has another way of doing it [3], I haven’t tested if that works as the dbus method works well enough for the moment.
Also calls can be scripted via the following command:
xdg-open tel://+61400000000
My aim is to get contacts synchronised via my own cloud service. Nextcloud is supposed to be able to do this. It’s been years since I first tried this, my most recent serious attempt at Nextcloud was in 2021 [4] and I couldn’t get the Android app for NextCloud to connect. Since then I have made more recent attempts and been unable to get the Android or Linux desktop clients to connect to it.
A friend gave me a test account on his Nextcloud server which allowed me to connect the Linux desktop app, his hypothesis was that it was somehow related to using Debian and that his server worked because it was on Ubuntu. I have since installed my own Nextcloud test server on the Ubuntu variant used by the Oracle cloud VMs which had the same apparent problem. I conclude that it’s not Debian at fault but something related to how I configured it.
In the meantime after a couple of months of having no named contacts I exported the contacts from my Android phone as a VCF file and imported them into the Gnome contacts program. I had to run “killall chatty” for it to get the names for the contacts, but the phone call program found them without needing to do that.
A missing feature of Chatty (the default SMS and Jabber program for Phosh/Phoc systems) is archiving old messages. I use Chatty to receive Jabber messages from my monitoring system which can be a lot of messages. The following shell code deletes all Jabber messages older than 2 days. Note that this relies on “type=3” matching Jabber messages which I’m not sure is going to be the case on all systems or all versions of Chatty.
for ID in $(echo "select id from users where type=3;" | sqlite3 ~/.purple/chatty/db/chatty-history.db); do
  echo "delete from messages where sender_id=$ID and time < unixepoch('now') - (48 * 3600);" | sqlite3 ~/.purple/chatty/db/chatty-history.db
done
The following shell code extracts a dump of all messages from Chatty.
echo "select messages.id,users.username,users.alias,messages.body from messages inner join users on messages.sender_id=users.id;" |sqlite3 ~/.purple/chatty/db/chatty-history.db
An update to the Chatty program for SMS and Matrix has made it crash repeatedly. There is a request in the list for Chatty upstream to have a systemd-user unit to restart it which when implemented will reduce the scope of the problem (but not solve it). I've setup a monitoring system that uses notify-send to notify me when Chatty isn't running or when 4G data turns off (a recurring problem). This crashing is allegedly due to Jabber so I installed Dino-IM for Jabber and have for the moment at least stopped using Chatty for Jabber.
It turned out that having Chatty not do Jabber didn't stop it crashing. However having alerts separated from SMS can be convenient and also my long term plan is to use a phone with Plasma Mobile and Spacebar (the SMS program for Plasma Mobile) doesn't do Jabber. So I will continue using Dino-IM.
echo "delete from message where time < unixepoch('now') - (48 * 3600);" | sqlite3 ~/.local/share/dino/dino.db
I put in the following cron job to stop this log file from using all the storage space:
1 0 * * * echo -n > /home/furios/.local/share/andromeda/data/system/uiderrors.txt
I gave up on attempts to force the Wifi configuration to have a fixed MAC that I could use for a fixed IPv4 address so I manually configured the address.
I've had problems with the reliability of the 4G service, sometimes it stop working and I need to stop and restart it. I setup my etbe-mon monitoring system on the phone [5] and configured it to ssh to localhost and run notify-send to send a local notification. This means I get notified if my phone loses net access and can't access regular monitoring. Then to monitor the 4G connection (which I want to have working even when Wifi is connected) I had the following monitor line:
monitor ping.monitor -I ccmni1 -c 5 8.8.8.8 ;;
That uses the ccmni1 interface for pinging 8.8.8.8 (Google DNS). That worked for a while but I discovered that sometimes the interface for 4G would change to ccmni2, so I put the following monitor script under /usr/local/mon.d:
#!/bin/bash
DEV=$(route -n|grep ^0.0.0.0.*ccm |sed -e s/^.*ccmn/ccmn/)
exec /usr/lib/mon/mon.d/ping.monitor -I $DEV -c 5 8.8.8.8
I couldn't get Tokodon to work, not the native package, not running in a Debian/Testing container, and not running a Flatpak. It seems that this is all graphics library issues. So I wrote a Perl program to run "toot notifications &-json" and then send the relevant parts of the output via XMPP. As I already use XMPP for server monitoring there's no extra effort to have an extra account and use it for notifications about Mastodon activity. The Perl script is at the bottom of the post and won't be in the RSS feed.
At some future time I may change the script to send the notifications by Matrix instead to have all my social media stuff in the same place.
#!/usr/bin/perl
# depends on Debian packages: toot libjson-pp-perl go-sendxmpp
use strict;
use JSON::PP;

my $homeurl = "https://mastodon.nzoss.nz/";
my $lastfile = "mast/last_id";
my $xaddr = "russell\@coker.com.au";

my $jsontxt;
while()
{
  $jsontxt .= $_;
}

my $data = decode_json($jsontxt);

my $last_id = 0, my $new_last_id;
if(open(ID, "<$lastfile"))
{
  $last_id = ;
  close(ID);
}
$new_last_id = $last_id;

for(my $i = 0; $data->[$i]; $i++)
{
  my $id = $data->[$i]{id};
  if($id <= $last_id)
  {
    next;
  }
  if($id > $new_last_id)
  {
    $new_last_id = $id;
  }
  open(XMPP, "|go-sendxmpp $xaddr") or die "Can't send XMPP";
  my $type = $data->[$i]{type};
  print XMPP "type: $type\n";
  print XMPP "their_url: $homeurl\@$data->[$i]{account}{acct}\n";
  print XMPP "display_name: $data->[$i]{account}{display_name}\n";
  if($type ne "follow")
  {
    print XMPP "status_url: $data->[$i]{status}{url}\n";
    print XMPP "content: $data->[$i]{status}{content}\n";
  }
  print XMPP "created_at: $data->[$i]{created_at}\n";
  print XMPP "\n";
  close(XMPP);
}

open(ID, ">$lastfile") or die "Can't write to $lastfile";
print ID $new_last_id;
close(ID);
30 October, 2026 12:13PM by etbe
Before the US and Israel started attacking Iran at the end of February the petrol prices in Australia were around $1.70/L, which for American readers is roughly equivalent to $US4.64/Gal. By the 11th of March the prices were around $2.19/L. Over the same time period Diesel went from around $1.77/L to $2.40/L. The 11th of March prices weren’t necessarily unreasonable prices. In mid March it was reasonable to expect that the US would stop doing such ridiculously stupid things and make a deal with Iran to allow oil to be transported.
But every time you think there’s a limit to Trump’s stupidity (and the incompetence of people around him who don’t point him in the right direction) they do something worse. So now we have the Strait of Hormuz almost entirely closed cutting off oil from Kuwait, Qatar, and UAE. The Bab al-Mandab Strait is closed to Saudi linked ships and the Saudi East-West pipeline is closed so once the Yanbu storage tanks are empty there won’t be much if any oil from Saudi Arabia for some time. So world oil supplies will be significantly reduced for a long time.
Currently the petrol prices in Melbourne are around $2.30/L and Diesel prices around $2.70/L, not much more expensive than it was in March in spite of all the extra problems both militarily and diplomatically since then. Those prices have been steady for over a month.
The blockade of the Strait of Hormuz could be ended fairly quickly and there are reports that a lot of the oil that used to go through it is being re-routed. The damaged infrastructure throughout the middle east can’t be fixed in a hurry. The Bab al-Mandab Strait probably can’t be opened quickly as the Houthis probably don’t have a centralised command structure that allows someone to order a ceasefire and have it stick. So we can expect a massive reduction in world oil supplies for a while, which given the way the US is going could be at least until after the mid-term elections (November this year) and possibly until after the 2028 elections. After that oil production will be reduced for another year or two to rebuild infrastructure.
When supply can’t meet demand there are three options. Supply can be rationed, demand can be decreased by increasing the prices, or it can be used up and we run out. Running out of fuel is a really bad option as fuel is needed for producing and transporting food and for most things that are important to a society.
Governments of first world countries seem unable to deal with the situation properly. Dealing with it properly requires either rationing or increasing the prices. Instead governments have been more interested in artificially keeping the prices down.
Currently in Australia and most countries a significant portion of public transport depends on Diesel fuel. Diesel is needed for most buses and for long distance trains. Most taxis run on petrol. As far as I know all emergency service vehicles run on Diesel or petrol as well as most military vehicles. So things will get really bad quickly if fuel runs out entirely. It’s not just personal cars that are affected.
We aren’t going to get the majority of tractors converted to electric power any time soon. Google search results suggest that tractors last an average of about 25 years but casual observation of working equipment on farms suggests a longer life than that is common. Some tractors could be retrofitted to be electric but many will end up being scrapped as part of a conversion while farmers are already having financial problems. It would probably be optimistic to expect that half the tractor use could be done with electric tractors in 10 years time unless there are significant government subsidies. To get the farming and food production industries adapted for electric operation in a few years would be possible but it would take a level of national mobilisation that only happens during wartime.
As a long term solution we need to have more electric vehicles in every category. We need electricity for all train lines to replace Diesel locomotives. We need better trains between cities to reduce the need for aeroplanes, electric aeroplanes are being developed but we aren’t there yet. We need all essential services to be run with electric vehicles including farming, food transport, emergency services, and everything related to the medical system (including personal cars for healthcare workers). We also need mining vehicles powered by electricity so we can have the entire industrial system running without fuel. None of this is going to happen in time for this crisis.
Electric buses are being introduced in Australia and many taxis are electric. The recent significant increase in the use of electric cars probably includes a reasonable portion of healthcare workers and other essential workers. This gives us the potential to survive fairly severe reductions in the fuel supply without everything collapsing. But we have a significant lack in electric police cars and in electric trucks for food delivery.
In the short term we need to significantly reduce the use of fuels, there is no other way to keep the food supply and other essential parts of society working. We could try rationing but I think that should be a last resort. The news reports of a de-facto petrol rationing system in Crimea and parts of Russia are not positive, significant resources are wasted in long queues for petrol and there is public disorder caused by disputes about position in the queues. The level of sanity in the population seems to have dropped significantly since the fuel crisis of 1979, any fuel rationing that is implemented now would get the same sort of opposition from Qanon types as Covid vaccines and lockdowns did in recent times.
So the best viable option seems to be to reduce demand by increasing prices. $2.30/L as a common price with occasional spikes of $2.50/L isn’t sufficient to do that. If the price increased to $3.50/L, twice what it used to be (equivalent to $9.50/gallon for Americans) then it would provide a real incentive for people to reduce fuel use. That would have to be combined with the type of remote work allowances that were in place when Covid19 was first spreading. But I think that all politicians are too weak to do such things. The media have demonstrated that nowadays the best we can expect is that they will treat both sides as equal even when facts clearly support one side, so we can’t expect the media to report on impending fuel shortages and demand policy changes to address them.
We should have higher taxes on fuel that will continue past the resolution of the current crisis caused by the attacks on Iran to provide incentives for the purchase of electric cars and for manufacturers to make more fuel efficient cars. Currently people are basing car ownership decisions on the expectation that petrol will go back to something under $2/L and we need to have a government guarantee that it won’t happen.
People always complain about poor people who can’t afford to drive if petrol is expensive but that could be addressed by increasing the minimum wage and social security payments. But a large portion of the people who complain about the hardship poor people may face when fuel prices are discussed are against increasing the minimum wage so I don’t think they are being honest.
Another common complaint is about the difficulty driving long distances in rural Australia when there isn’t sufficient charging infrastructure for electric cars and therefore rural people including farmers getting hit by high prices of fuel. There could be a rebate scheme for farmers etc, government subsidies for farmers is nothing new.
I expect the governments of most first world countries to try to keep fuel prices low and do very little to try and decrease demand. China will probably do some things to reduce fuel use and being the world’s largest oil importer this will make a difference, but not as much as we need.
A related problem is that a lot of fertiliser is produced from petrochemicals and closing the strait of Hormuz cut off a significant portion of the world fertiliser supply. First world countries will outbid developing countries for fertiliser and fuel. Starvation in developing countries probably won’t get much news coverage until it leads to war.
This is not going to go well, it could be addressed if we had braver politicians and more honest media companies but that’s not the way things are going.
30 October, 2026 06:16AM by etbe
At the end of last year I paid $177.40 for a Radxa ROCK 5A GREEN RK3588S, 8-core CPU SBC, HDMI with 8K Output, WiFi 6 Support and Gigabit Ethernet, Single Board Computer [1] from AliExpress. I got the version with 8G of RAM as 4G didn’t seem enough and I didn’t feel like paying for the 16G or 32G versions. The prices excluding postage are $106, $130, $203, and $332 for the 4G, 8G, 16G, and 32G versions respectively. The $332 version is quite reasonably priced if you need to do some big compiles on ARM64. Since then the prices have changed by a few dollars but are almost the same (variations in postage will be greater than the price changes).
They provide modified versions of Debian/Bookworm and Debian/Bullseye [2] and an Android installation. The Debian setup includes a custom kernel, bootloader, some configuration packages including for ALSA, and some firmware.
I installed Bookworm and upgraded it to Trixie (the current Debian release). There were some conflicts with some radxa packages that contained the same files as Trixie packages but didn’t have a package conflict but it was not a big deal. It would be nice if Radxa updated their setup to Trixie and it wouldn’t be that difficult for them to do so.
The board has an expansion bus which apparently can be used for NVMe. It also has an option for a EMMC module. But if you get the default configuration then the only boot device supported is a micro SD card.
One of the aims of purchasing this card is for testing 8K monitors, but it turns out that there are no TVs that will take 8K input on sale in Australia [3].
The next thing I considered doing is running it for playing movies on a 4K but it turns out to not support HDMI audio (at least not with the supplied drivers) and has no other audio support. Apparently boards like this have a common use case of digital signs where audio isn’t required.
I had this post in draft for a year because I planned to write more, but I haven’t come up with anything. It’s not an exciting device. Handy to have another ARM test and build system and handy to be able to test high resolution video with a portable device but I don’t use it for much. I guess “just works in a boring way” isn’t a bad review.
30 October, 2026 05:56AM by etbe
The diffoscope maintainers are pleased to announce the release of diffoscope
version 336. This version includes the following changes:
[ Chris Lamb ]
* Drop Recommends: guix from the diffoscope-minimal package.
  (Closes: #1114739)
You find out more by visiting the project homepage.
pre-commit is a tool that is often a prerequisite for contributing to Python upstream projects. It installs as a git pre-commit hook and runs various checks on commit, using tools installed in a set of virtualenvs that it automatically manages.
In other words, it is a Remote Code Execution engine running with the
permissions of your own user, and with read and write access to all your
information (including, say, ~/.ssh or ~/.netrc). If you are lucky, and for
as long as you're lucky, it will perform useful tasks on your code.
The recent eMudhra certificate situation, where I learnt how Python, as well as several other ecosystems, likes to embed CA certificate bundles in virtualenvs, caused my tolerance for this to lower to a point where I felt the need to limit pre-commit's reach.
However, I didn't want to end up with another containerized OS tree that it's
then my responsibility to manage, and I tried to go the
bubblewrap way, so that the
environment where pre-commit runs will get the same security updates as the
rest of my system.
The result is a pre-commit wrapper script that:
.git directory is readonly, so that changes in the code can be
reliably detected via git diffHere's a breakdown of the bwrap options I used so far.
Set up usual filesystem expectations:
    --ro-bind /usr /usr \
    --symlink usr/bin /bin \
    --symlink usr/lib64 /lib64 \
    --symlink usr/lib /lib \
    --proc /proc \
    --dev /dev \
Make the working directory and pre-commit's environments storage available and writable:
    --bind ${CURDIR} "$GUEST_DIR" \
    --bind ~/.cache/pre-commit "/home/${USER}/.cache/pre-commit" \
    --chdir "$GUEST_DIR" \
Forward git's configuration:
    --ro-bind /etc/gitconfig /etc/gitconfig \
    --ro-bind ~/.gitconfig /home/${USER}/.gitconfig \
Make .git writable (pre-commit needs to stash, for example), but use a tmpfs
overlay so that the writes don't persist:
    --overlay-src "$CURDIR/.git" \
    --tmp-overlay "$GUEST_DIR/.git" \
Remove access to everything except the above. Prevent keystroke injection at
the terminal. Propagate ^C.
    --unshare-all \
    --new-session \
    --die-with-parent
If network is needed:
    --share-net \
    --ro-bind /etc/resolv.conf /etc/resolv.conf \
    --ro-bind /etc/ssl/certs/ca-certificates.crt /etc/ssl/certs/ca-certificates.crt
To run it, you can set up the wrapper script to run with a higher priority in
$PATH, but you need to edit .git/hooks/pre-commit to remove the first
branch of the if that, frustratingly, tries to run it as python3 -m
pre_commit.
I'm looking forward to a time where it becomes stadard practice to manage user
commands this way: why should a desktop solitaire game have access to ~/.ssh?
Or network? Why is it still normal, in 2026, to run a Desktop system like that?

Debcraft is a tool that automates most of the repetitive and error-prone steps related to Debian packaging. It makes it easy to build .deb packages from source without having to manually prepare build environments. It clearly shows what changed in the build artifacts between two builds, automates parts of importing new upstream versions, and can automatically apply repetitive fixes to the packaging source code, including committing them in git.
While doing all of this, it also explains what it does and helps users learn best practices in Debian packaging, making the overall experience much easier and more fun than with any other tool before, while also being secure and fast.
Debcraft can be installed simply by running apt install debcraft on a recent version of Debian or Ubuntu. Check with debcraft --version that you have 1.0.0 or newer. The latest version can also always be installed from source at salsa.debian.org/debian/debcraft (does not require compiling anything).
Debcraft was designed to offer the following three main benefits:
Build any Debian/Ubuntu package by simply running debcraft build in the checked-out Debian packaging git repository.
If the orig upstream source code tarball is neither already present nor available on a pristine-tar branch, the exact upstream tarball is downloaded from the Debian archive.
Users are spared from having to manually prepare ahead or maintain build environments. Debcraft builds create a container on-the-fly (both Podman and Docker supported), built using the target Debian or Ubuntu suite in debian/changelog and with exact build dependencies from debian/control.
Commands debcraft improve, debcraft test and debcraft update automate recurring package maintenance tasks and help maintainers produce high-quality, up-to-date packages, run Salsa CI, pass autopkgtest in Debian CI, and stay in sync across Debian archives and packaging git repositories.
The command output is (relatively) easy to read, and it also teaches users about Debian packaging in context.
Container layer caching is utilized to make builds and re-builds blazingly fast.
If an apt-cacher-ng instance or equivalent is present, it will automatically be used.
Debian packages that support ccache or sccache build even faster.
The build phase happens inside hermetic containers with no network access. This ensures all dependencies are properly managed and that the built binaries are as trustworthy as the source code they were built from.
Using containers also protects the host system from getting polluted with extra development libraries, and adds an extra layer of protection to prevent anything malicious in the source code from accessing secrets on the host system.
The additional logs provided by Debcraft also help audit changes in Debian package sources and build artifacts.
See the Debcraft README.md for details on how this was implemented. I also previously wrote Debcraft - Easiest way to modify and build Debian packages, which explains the motivation and design in more detail.
The first commit in the git repository is from 2020 under the name debuildr. The project was renamed to Debcraft in a commit on December 8th, 2023. I have been developing this tool fairly actively since 2024 and using it for all my packaging, “dogfooding” so to say.
There have also been plenty of collaborators. In total, 13 people have contributed code across 21 MRs and PRs on Salsa.d.o, GitLab.com and GitHub.com.
Now, in October 2026, it was time to release Debcraft v1.0 as it has had extensive real-world use and iteration based on countless different packages and multiple users. Users have included both experienced fellow Debian Developers and lots of people who just started learning how Debian packaging works. As I mentor dozens of new contributors to Debian, I have seen that the latter group seems to benefit the most from Debcraft and its ease of use and built-in guidance, while to the more experienced developers the main benefit is having less details to remember and doing less mistakes.
Try it: apt install debcraft, then run debcraft build in a checked-out Debian packaging repository. If you run into a problem, file a report or submit an improvement. New contributors can look for issues marked good first issue.
The code is intentionally written entirely in shell script to keep the barrier to code contribution as low as possible. It is also very easy to debug, as any command can be run with --debug to emit step-by-step information about what it is doing, and being Bash scripts, injecting set -x anywhere in the code will emit an even more detailed trace of every subcommand executed.
By the way, if you aspire to become a Debian Developer, and want to follow my examples in using state-of-the-art tooling and collaborate using salsa.debian.org, feel free to reach out for mentorship. I am glad to see more people contribute to Debian!
Earlier this week I had a coaching session with Protesilaos, where we focused on health and wellness. I took some notes during our call, which I expand on here, and share with Prot's permission. I've been paying more serious attention to my health this year, and our discussion was in the context of me striving to live a healthier life. These notes are shared in the hope of being useful and are not professional advice; for medical advice please consult a licensed physician.
Update 24 October 2026: Prot published a note about our discussion on his website: Healthier lifestyle with Amin Bandali
Life in today's fast-paced world can feel busier than ever, where every day is packed with a myriad of activities and tasks that need to be done, or tempting distractions that pop up seemingly randomly, with hardly a moment to spare. Despite that, or perhaps because of that, it's worthwhile to make time for ourselves and the various aspects of our health.
As embodied souls, our bodies condition our minds. We take care of our body so we can take care of our mind. As humans we evolved for an active lifestyle out of survival necessity. In today's society many of us have sedentary office jobs that involve sitting for long periods of time. It's especially important that we try and make time for some regular physical activity like exercising and resistance training, to help build and retain muscle mass and mobility as we age. Fitness does not have to be the end goal that takes over our life, though there is nothing wrong with that if fitness is one's central goal e.g. as a personal trainer. Rather, for someone like me with other primary goals, my reason to exercise is to help live a healthier life, so I could spend quality time with my loved ones and carry out my responsibilities with a healthy body and mind.
Prot mentioned that our health is directly dependent on the following four factors:
Thus compromising any of these - for example, eating greasy food or drinking alcohol - would undermine the gains from exercising.
While pursuing fitness, it's important to have sustained effort so that the body remains active and the mind is not distracted, and equally important to have sustainable effort so that we don't suffer injuries and not make the pursuit of fitness burdensome financially.
Calisthenics is a key part of the strength training activities Prot practices, in addition to the physically intensive work he does on his land.
Calisthenics [...] is a form of strength training that utilizes an individual's body weight as resistance to perform multi-joint, compound movements with little or no equipment. Calisthenics are popular for their convenience, as they require little to no equipment and can be performed anywhere.
Calisthenics can be done progressively, starting small and building in intensity and duration over time. It is also economically/financially sustainable. These calisthenic exercises are a good starting point (barring existing injuries in the related areas):
Aim to perform each exercise in 3 sets of 10 repetitions, but it's perfectly okay to start with fewer and gradually build up. The exercises should be done around the same time everyday, so that there is enough time for the muscles to rest and recover for the next day. Doing them at night then again the next morning, for instance, would be too short of a time period and not enough for the body to recover. It's also vital to get enough sleep each night to make sure the body can properly rest and be energized the next day.
FoodAs mentioned earlier, it's crucial to pair exercise with a healthy diet. I found Prot's programming metaphor for food interesting: similar to how it takes more time and effort for us to process and understand complex source code, breaking down and processing complex foods is similarly more difficult for the body. Prot does not eat fried food, and recommends avoiding sauces as much as possible: greasy, salty, and creamy extras make food more irresistible. They tend to make one want to eat more than what the body needs, and are to be avoided in isolation but especially in combination. In keeping ingredients close to their natural states, not overdoing things, and not eating more than the body needs, Prot extends his philosophy of simplicity and moderation to cooking.
In addition to eating healthy meals, we need to apply similar consideration to snacks: avoiding overly salty or sugary snacks, and choosing healthier ones. Nuts can make great snacks in small quantities, especially almonds and walnuts, if one's not allergic.
In addition to the inherent healthiness of the food or snack, Prot also suggests paying attention to methods of preparation. For instance, regarding concentration or distillation: juices, even when freshly squeezed from fruits, might have more of the fruits' sugar than its pulp and other beneficial parts. Additionally, chewing triggers biological responses in our body which for example can reduce stress, and release satiety hormones to help avoid overeating. So, Prot suggests to just eat the fruits themselves.
Regarding weight loss, it will occur naturally as we introduce exercise into our routine, and pay closer attention to what we eat and drink. It's important to lose the weight slowly to condition our body to the new reality as it changes. Shortcuts tend to either not work, or have negative consequences. By going through the process slowly and with regularity, we gradually retrain our muscle memories and adjust our habits so we can maintain the lower weight and the healthier lifestyle. Regularity is key: it's better do a little everyday, than do a lot on only two days. It helps us develop the attitude that the exercise is part of our regular effort that we do consistently all the time.
Working on wellness and living healthier is a matter of moderation, and building capacity over time. I will give it the time and attention it needs, without rushing, and enjoy the journey to becoming a healthier version of myself.
Take care, and so long for now.
The diffoscope maintainers are pleased to announce the release of diffoscope
version 335. This version includes the following changes:
[ Chris Lamb ]
* Support the dumppdf binary being called dumppdf.py on the host system.
* Update copyright years.
* Fix a silly "prepend" typo.
You find out more by visiting the project homepage.
As promised, the last one (for now?), and this one blew my mind the first time I saw it:
    var_v0 = sp4014;
    if ((s32) sp4014 < 0) {
        var_v0 = sp4014 + 0x7FF;
    }
    temp_s1 = 0x800 - (sp4014 - (((s32) var_v0 >> 0xB) << 0xB));
There's actually two things going on here. First, the compiler is faking a signed division using shifting (which rounds down) as a building block: If the value is negative, then you add a bias to make shift into round-up. (The right-shift by 0xB, or 11, is exactly a division by 0x800.)
So this means what we're looking at is:
    var_v0 = (s32) sp4014 / 0x800;
    temp_s1 = 0x800 - (sp4014 - var_v0 * 0x800);
which reduces further to:
temp_s1 = 0x800 - ((s32) sp4014 % 0x800);
Tada. That's it. Now you know all the tricks, except those that I don't know or that I forgot. You don't need the LLM. Have fun. :-)
Edit: Corrected a thinko; of course, MIPS has signed division. This is for power-of-two optimizations only.
Occasionally, you'll see code like this (after initial cleanup):
    var_v0_2 = crc & 0x80000000;
    do {
       if (var_v0_2 != 0) {
           crc = (crc << 1) ^ 0x1EDC6F41;
       } else {
           crc <<= 1;
       }
       var_a0 += 1;
       var_v0_2 = crc & 0x80000000;
    } while (var_a0 < 8U);
The thing with var_v0_2 is unnatural. GCC sometimes does these loop rotation tricks, seemingly
to save registers (don't ask me how exactly it does). You want to un-rotate
back into:
    do {
       var_v0_2 = crc & 0x80000000;
       if (var_v0_2 != 0) {
           crc = (crc << 1) ^ 0x1EDC6F41;
       } else {
           crc <<= 1;
       }
       var_a0 += 1;
    } while (var_a0 < 8U);
and then of course, you can clean up the rest:
for (i = 0; i < 8; ++i) {
    if (crc & 0x80000000) {
        crc = (crc << 1) ^ 0x1EDC6F41;
    } else {
        crc <<= 1;
    }
}
Last one tomorrow, I think.
Linux cgroups has been used for a while to group processes and control their access to certain system resources. One of those resources is memory, through the use of memcg. That control is dynamic, allowing for cgroups to setup a minimal and a maximal amount of memory, as well as low and high thresholds, which will control the reclaim process.
But what about device memory that is not available as system RAM? Memory that is not available to the Linux page allocator? One of those device memories is GPU VRAM.
That's where the dmem cgroup controller comes in. Introduced in Linux 6.14, it was first adopted by the Intel Xe driver. In Linux 6.15, AMD amdgpu driver also adopted it. In 7.3, it was adopted by nouveau.
Such a cgroup controller allows the system to be configured such that a workload, be it a browser, a game, or another GPU rendering process can have some minimal VRAM available. Or it can prevent one of these processes from using all VRAM, preventing your compositor from using it, for example.
Let's go through the system knobs that are available to control this and what's new in Linux 7.3.
Since a given system might have multiple GPUs, there might be multiple device memory regions. So, on dmem, each such region is described by a name. Every dmem cgroup setting file will contain one line per region. One of those files shows the capacity of each region in bytes and is present only in the root cgroup.
After enabling the dmem cgroup with the following command:
# echo +dmem > /sys/fs/cgroup/cgroup.subtree_control
One can inspect the capacity of any available regions by looking at dmem.capacity at the root cgroup:
# cat /sys/fs/cgroup/dmem.capacity
drm/0000:03:00.0/vram 8573157376
That shows that the GPU at PCI address 0000:03:00.0 has a 8176MiB VRAM dmem region.
When introduced at 6.14, the following settings were available.
In every dmem cgroup, including the root cgroup, the dmem.current is a read-only file that shows the current usage of each region by the given cgroup.
# cat /sys/fs/cgroup/user.slice/dmem.current
drm/0000:03:00.0/vram 292757504
Here, it shows that user.slice cgroup is currently using above 292 MB of VRAM.
# cat /sys/fs/cgroup/dmem.current
drm/0000:03:00.0/vram 311377920
Here, we can check that total system usage is above 311 MB.
Excluding the root cgroup, dmem cgroups can control the maximal number of bytes that can be allocated from a region by processes in that cgroup. If an allocation moves the usage above the max setting, it will be refused. In that case, the allocation might be attempted at system memory or it might trigger eviction, depending on the allocation parameters and the driver.
Here, the max value has special meaning, which is unrestricted usage.
# echo drm/0000:03:00.0/vram 536870912 > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram 536870912
# echo drm/0000:03:00.0/vram max > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram max
dmem.min, also not available on the root cgroup, will control the eviction process - when memory needs to be moved out of VRAM to make room for other VRAM allocations. If an object belongs to a cgroup which is using less than its min setting, it will not be considered for eviction. It effectively works as a hard protection such that the cgroup can use at least the minimal setting.
Given multiple cgroups may set a minimal value that exceeds the device memory capacity, it computes an effective minimal depending on the hierarchy.
While dmem.min works as a hard limit, dmem.low is a soft limit that will prevent eviction in case other objects from different cgroups are available for eviction. That is, the system will try to evict from different, possibly unprotected cgroups, before it tries to evict from a cgroup if evicting would leave its usage below the value set as dmem.low.
Some new changes have been recently introduced in the dmem cgroup controller and its integration with GPUs.
One of those is a new read-only file, dmem.peak, which was introduced to allow the peak usage of a region in a cgroup to be inspected.
Also, Linux 7.3 fixed certain scenarios where a given cgroup would not be able to allocate VRAM up to its minimal or low limits if other processes had already allocated most of VRAM, even though they had no such limits set.
Changing multiple regions' settings in a single write was possible before 7.3, but it was prone to failures which would not be reported to userspace and might have left the values partially updated. Starting with 7.3, only one region may be updated per write.
And, finally, prior to 7.3, setting dmem.max in a cgroup that was using more than the new setting would silently fail. Now, there is a mechanism that allows a reclaim mechanism to be triggered. That way, when a process writes to dmem.max and sets a maximal value below the current usage, it will wait (unless O_NONBLOCK is used) for the reclaim process to move objects out of VRAM until the usage gets below the maximal value. If that is not possible for some reason, the setting will still be in place, restricting further alloctions by that cgroup.
We're nearing the end soon, I promise. Here's one that I see all the time:
     ...
         } else {
             var_t0_5 = temp_a0_3 - 0x140;
             var_a2_5 = 0xA0 - temp_a3_5;
             goto block_45;
         }
     } else {
         var_t0_5 = 0xA0 - temp_a0_3;
         var_a2_5 = temp_a3_5 - 0x118;
block_45:
         var_v0_3 = var_t0_5 + 0xA0;
         var_v1_4 = var_a2_5 + 0x78;
     }
So, eh, what's that goto doing there? What happened was that the compiler helpfully figured it could help with some tail deduplication; someone wrote the same code twice, and the compiler figured taking the cost of a branch was better than keeping it duplicated. (In a sense, it's the opposite of inlining. Ish.) In most cases, it's as simple as copying the block and then you can remove the label:
     ...
         } else {
             var_t0_5 = temp_a0_3 - 0x140;
             var_a2_5 = 0xA0 - temp_a3_5;
             var_v0_3 = var_t0_5 + 0xA0;
             var_v1_4 = var_a2_5 + 0x78;
         }
     } else {
         var_t0_5 = 0xA0 - temp_a0_3;
         var_a2_5 = temp_a3_5 - 0x118;
         var_v0_3 = var_t0_5 + 0xA0;
         var_v1_4 = var_a2_5 + 0x78;
     }
Sometimes, these are nested, with multiple tails goto-ing into each other, so in that case, you'll need to reduplicate multiple times. Make sure you actually come out on the correct side afterwards, though.
As an extra complication, the code is deduplicated not on the C statement level, but on
RTL instructions, so if you're calling functions with five parameters
of more (which requires pushing parameters onto the stack), m2c can
get really confused and start throwing M2C_ERROR() at you on the
receiving side because it's not clear at all where the parameters
would be coming from.
Another new and exciting version of our still-new package myman reached CRAN this morning, and has been built for r2u and on r-universe. The matching Python package has also been updated. The package offers twenty one hundred eighty four “My man …” posts by Kevin Kruse made on bsky during the summer of 2026. Each wave picked at one particular public persona. This package wrapse these up in the style of packages like fortunes or gaussfacts.
This release regroups two new waves of posts mocking, respectively, Peter Thiel and Michael Tracy, and make a small update to continuous integration. The short NEWS entry for this release follows.
Changes in version 0.12.0 (2026-10-18)
New waves eleven (100 posts) and twelve (100 posts) made last week; total is now 2184 posts
Small update to continuous integration
Courtesy of my CRANberries, there is also a diffstat report for the most recent release. More information is available at the repository or the package page.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
I have just released a new version of pcsc-lite 2.5.3.
pcsc-lite is a Free Software implementation of the PC/SC (also known as WinSCard) API for Unix systems. It provides an API for using smart cards and smart card readers.
18 October 2026
pcscd.service: preserve card sessions across polkit restarts
correctly decode all ATRs (fix the fix suggested by AI)
Fix authorization for uid > 65536
18 October, 2026 02:27PM by Ludovic Rousseau
Yet another way of writing for loops:
    var_a2_4 = ...
    if (var_a2_4 < 0x78) {
        ...
        do {
            ...
            var_a2_4 += 1;
        } while (var_a2_4 < 0x78);
    }
This extra if is merely there because the compiler wasn't able to prove that the variable didn't start below the bound, so it can't rewrite the while-do to a do-while without that extra check. So the rewrite still reads:
for (var_a2_4 = ...; var_a2_4 < 0x78; ++var_a2_4) {
    ...
}
possibly with the initializer skipped, if it comes from something complex earlier.

Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language–and is widely used by (currently) 1370 other packages on CRAN, downloaded 49.4 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 735 times according to Google Scholar.
This versions updates to the 15.6.2 upstream Armadillo release made yesterday. It, along with 15.6.1 release we incorporated earlier, addresses only minor issues and should not present any user-facing changes. As usual, we did run full reverse-depdency checks against the over 1300 ackages, and did not find anything. As usual, we aim to accommodate the desired CRAN cadences for uploads and try not to exceed six in six months—so we did not ship 15.6.1-1 there. The package has also already been updated for Debian, built for r2u and r-universe, and will build shortly at CRAN for the different binary releases.
All changes since the last CRAN release follow.
Changes in RcppArmadillo version 15.6.2-1 (2026-10-16)
Upgraded to Armadillo release 15.6.2 (Medium Roast Cortado)
- Faster inplace addition of
eye()expressionsChanges in RcppArmadillo version 15.6.1-1 [github-only] (2026-10-02)
Upgraded to Armadillo release 15.6.1 (Medium Roast Cortado)
- Fix for failures in
pinv()when using the (non-default) "std" method
Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
A brand new release 0.1.17 of the RcppSimdJson package is now on CRAN, and has been built for r2u and on r-universe.
RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is ‘faster than CPU speed’ as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon.
This release is a small increment relative to the 0.1.6 release last week that got us (upstream) version 5.0.2 with many notable changes and sizeable speed gains on all fronts, including the interface from R. However, this failed to compile at CRAN on macOS x86_64 as the machine is setup for only partial support of C++20: no ranges, no concepts. So we now test, and fall back to C++17 if the test compilation fails. Upstream, meanwhile, already got to 5.0.5 which is included. It also gets us improved handling of disabling pragmas which we hope will survive CRAN checks.
The brief NEWS entry for this release follows.
Changes in version 0.1.17 [unreleased] (2026-10-xx)
Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.
A complete feed is available in any of your favourite syndication formats linked by the buttons below.


Last updated: 14 Nov 2026 08:30
All times are UTC.
Contact: Debian Planet Maintainers

EmacsConf 2026 community panel - my comments
This is a recollection of my comments from the EmacsConf 2026 community panel recording session this past weekend, where the panellists took turns answering the proposed questions, one minute per question per panellist.
In addition to the live Q&A session planned for Saturday 12 December 2026 during EmacsConf 2026, all Emacs users and community members are invited to share their thoughts on the panel questions or other questions before or after the conference.
https://emacsconf.org/2026/talks/community/
I started using Emacs during my bachelor's studies. I actually learned about Vim first and was a Vim user, but I'd always found the configuration language (VimScript) a little bit clunky. Not long after, I discovered Emacs, and really loved reading and writing Emacs Lisp, so I stuck around.
In addition to reading and writing Elisp being fun and enjoyable for me, I love that Emacs has been a practical embodiment of software freedom, and I'm really fond of its surrounding culture of sharing freely. There's a lot to love and appreciate about Emacs, but as a practical personal example, I've been grateful for its excellent support for bidirectional text editing. It has empowered me to read and write in Persian, my mother tongue, with ease. (Persian has a right-to-left alphabet, like Arabic and Hebrew.)
As I continued experimenting and writing bits and pieces of Elisp to scratch my own itches, I felt compelled to share them freely as a way of giving back to the community that gave me so much.
For me, the community and the people that make it up are the main deal. Emacs wouldn't be where it is and what it is today without its people, so besides programming contributions, I've tried to contribute in that area as well, for instance by reviving EmacsConf with Sacha Chua back in 2019.
I don't physically have people near me who use Emacs, but I've connected with many folks in our online communities, often starting with an email or IRC message. Some of those relationships started as acquaintanceship and were developed into true friendship over time, and I'm grateful to have had those friends with me.
I would encourage Emacs, our community, to focus on the people. We're living in particularly difficult times, with various kinds of hardships and uncertainty in our lives. Let's strive to treat each other with kindness, empathy, and mindfulness as we continue working together.
There are great examples of other free software communities whose members have banded together and are strengthening each other and their community, as well as cautionary ones where community members have been tiring and driving out their fellow members. We could learn valuable lessons from both in how to take care of our people and ourselves.
I echoed the sentiments of my fellow panellists Prot and Til about doing more of the same in terms of continuing to uphold the standards of excellence and perseverance. Also, drawing inspiration from what bashbunni said, to lower the barriers of entry for people, for example through organizing different kinds of events, and experimenting with ways to make people's lengthy, elaborate Emacs configurations more tangible and accessible to others, to share various workflows and demonstrate what's possible with Emacs.
I look forward to your thoughts on these and other community-related questions.
Take care, and so long for now.
09 November, 2026 09:57PM